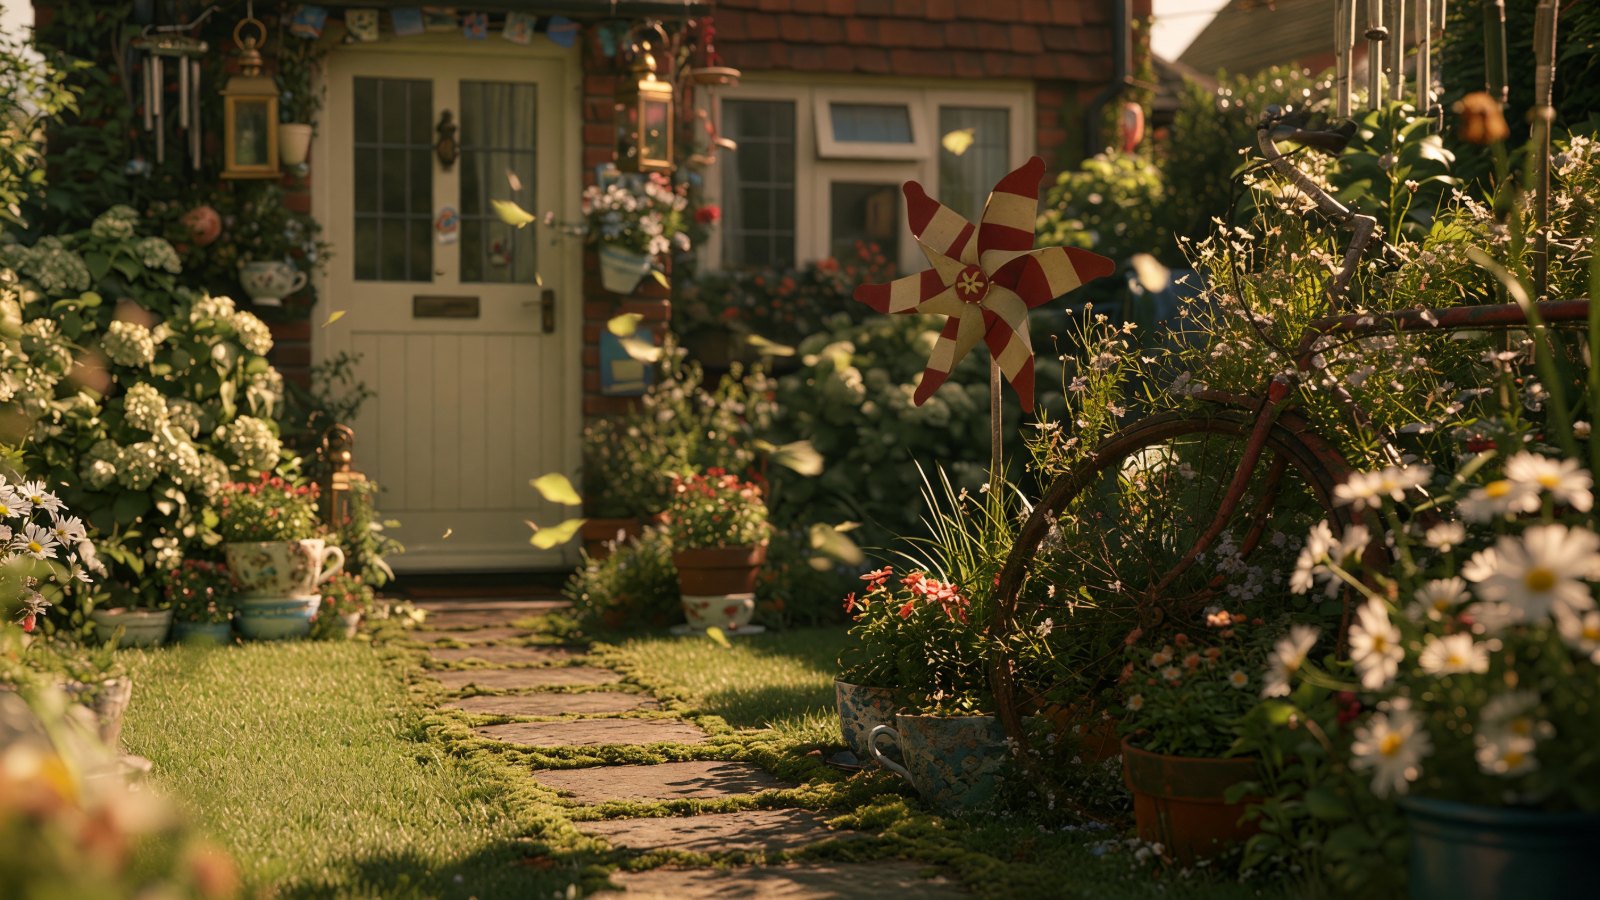<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://mito.ai/blog/feed.xml" rel="self" type="application/atom+xml" /><link href="https://mito.ai/blog/" rel="alternate" type="text/html" hreflang="en" /><updated>2026-10-02T11:45:17+02:00</updated><id>https://mito.ai/blog/feed.xml</id><title type="html">MITO Universe</title><subtitle>A curated space spotlighting AI-first creators — where art, technology, and culture intersect intentionally.</subtitle><author><name>The MITO Team</name></author><entry><title type="html">How to Make an AI Avatar of Yourself from One Photo</title><link href="https://mito.ai/blog/how-to-make-an-ai-avatar-of-yourself/" rel="alternate" type="text/html" title="How to Make an AI Avatar of Yourself from One Photo" /><published>2026-10-01T00:00:00+02:00</published><updated>2026-10-01T00:00:00+02:00</updated><id>https://mito.ai/blog/how-to-make-an-ai-avatar-of-yourself</id><content type="html" xml:base="https://mito.ai/blog/how-to-make-an-ai-avatar-of-yourself/"><![CDATA[<p>To make an AI clone of yourself you need three things: one good photo, about 20 seconds of your voice, and a script. In MITO that happens in <strong>Avatar Studio</strong>, which turns a single photo into a talking, blinking, lip-synced presenter. The whole setup takes roughly five minutes.</p>

<p>Here is the proof. “Welcome to MITO University. Today, we’re going to learn how to make AI clones of ourselves.” That is the opening line of our latest tutorial, and nobody said it. An AI clone did.</p>

<p>This is the full walkthrough, so by the end you can have one of yourself. Stick around for the last section, where we skip voice cloning entirely and make the avatar speak in your real voice instead.</p>

<hr />

<h2 id="what-you-can-use-an-ai-avatar-for">What you can use an AI avatar for</h2>

<p>Before the how, the why. An avatar earns its keep any time you need someone on camera but do not want to set up a shoot every time.</p>

<ul>
  <li><strong>Spokesperson videos</strong> for a product or a brand, without booking a studio.</li>
  <li><strong>Training and onboarding</strong> content, which is easy to update when the process changes and the old version is just wrong.</li>
  <li><strong>Localisation.</strong> The same video in another language for another region.</li>
  <li><strong>Short vertical clips at volume</strong> for TikTok, Reels and Shorts.</li>
</ul>

<p>We make a lot of long-form content for YouTube and Instagram, so we built a clone. Here is how.</p>

<hr />

<h2 id="step-1-open-avatar-studio">Step 1: Open Avatar Studio</h2>

<p>In MITO, open the left toolbar and click <strong>Avatar Studio</strong>, then hit <strong>Create an Avatar</strong>.</p>

<p><img src="/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/avatar-studio.jpg" loading="lazy" width="2000" height="884" alt="The MITO Avatar Studio landing screen: a close-up portrait behind the Avatar Studio wordmark, the line One face. Any script. Any language., and a Create an avatar button" /></p>

<hr />

<h2 id="step-2-choose-your-face">Step 2: Choose your face</h2>

<p>Two options here.</p>

<p><strong>Pick from the library.</strong> There is a long list of ready-made avatars, Alisa, Anina, Alec and plenty more. If you just need a presenter and it does not have to be you, pick one and move on.</p>

<p><strong>Upload your own photo.</strong> This is the one for making a clone of yourself.</p>

<svg class="ui-figure" viewBox="0 0 640 576" role="img" aria-label="The Avatar Studio picker: a row of four ready-made avatars from the library with an add-your-own button beside them, a drop zone reading Select your image with Select and Avatar buttons, and a voice row below">
  <title>Choosing a face in Avatar Studio</title>
  <desc>A selection ring moves across four ready-made avatars and comes to rest on the add-your-own button, the route you take to make a clone of yourself.</desc>
  <style>
    .ui-f { font-family: "Monument Grotesk", system-ui, sans-serif; }
    .ui-eyebrow { font-family: "Monument Grotesk Mono", ui-monospace, monospace;
      font-size: 12px; letter-spacing: 1.5px; fill: var(--text-low); }
    .ui-meta { font-size: 14px; fill: var(--text-low); }
    .ui-lead { font-size: 19px; fill: var(--text-high); }
    .ui-sub  { font-size: 15px; fill: var(--text-mid); }
    .ui-btn  { font-size: 16px; fill: var(--text-high); }
    .ui-panel { fill: var(--card); stroke: var(--border); }
    .ui-dash { fill: none; stroke: var(--border-mid); stroke-dasharray: 7 6; }
    .ui-stroke { fill: none; stroke: var(--text-mid); stroke-width: 1.6;
      stroke-linecap: round; stroke-linejoin: round; }
    .ui-av { fill: var(--background-mid); }
    .ui-av-rim { fill: none; stroke: var(--border); stroke-width: 1; }
    .ui-ring { fill: none; stroke: var(--accent-lime); stroke-width: 3; }
    @keyframes uiPick {
      0%,   13% { cx: 74px; }
      16%,  29% { cx: 197px; }
      32%,  45% { cx: 320px; }
      48%,  61% { cx: 443px; }
      64%, 100% { cx: 566px; }
    }
    .ui-ring { animation: uiPick 8s ease-in-out infinite; }
    @media (prefers-reduced-motion: reduce) {
      .ui-ring { animation: none; cx: 566px; }
    }
  </style>

  <rect x="1" y="1" width="638" height="574" rx="18" class="ui-panel" />

  <g class="ui-f">
    <text x="28" y="44" class="ui-eyebrow">AVATARS</text>
    <text x="612" y="44" class="ui-meta" text-anchor="end">See all</text>

    <defs>
      <clipPath id="avatarLib1"><circle cx="74" cy="118" r="46" /></clipPath>
      <clipPath id="avatarLib2"><circle cx="197" cy="118" r="46" /></clipPath>
      <clipPath id="avatarLib3"><circle cx="320" cy="118" r="46" /></clipPath>
      <clipPath id="avatarLib4"><circle cx="443" cy="118" r="46" /></clipPath>
    </defs>
    <g class="ui-av"><circle cx="74" cy="118" r="46" /><circle cx="197" cy="118" r="46" /><circle cx="320" cy="118" r="46" /><circle cx="443" cy="118" r="46" /></g>
    <image href="/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/avatar-lib-1.jpg" x="28" y="72" width="92" height="92" clip-path="url(#avatarLib1)" preserveAspectRatio="xMidYMid slice" />
    <image href="/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/avatar-lib-2.jpg" x="151" y="72" width="92" height="92" clip-path="url(#avatarLib2)" preserveAspectRatio="xMidYMid slice" />
    <image href="/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/avatar-lib-3.jpg" x="274" y="72" width="92" height="92" clip-path="url(#avatarLib3)" preserveAspectRatio="xMidYMid slice" />
    <image href="/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/avatar-lib-4.jpg" x="397" y="72" width="92" height="92" clip-path="url(#avatarLib4)" preserveAspectRatio="xMidYMid slice" />
    <g class="ui-av-rim"><circle cx="74" cy="118" r="46" /><circle cx="197" cy="118" r="46" /><circle cx="320" cy="118" r="46" /><circle cx="443" cy="118" r="46" /></g>
    <circle cx="566" cy="118" r="46" class="ui-dash" />
    <path d="M566 102v32M550 118h32" class="ui-stroke" />

    <circle class="ui-ring" cx="74" cy="118" r="53" />

    <rect x="28" y="192" width="584" height="268" rx="16" class="ui-dash" />
    <g class="ui-stroke" transform="translate(302 234)">
      <rect x="0" y="0" width="36" height="30" rx="5" />
      <circle cx="11" cy="11" r="3.5" />
      <path d="M3 27l10-10 7 7 5-4 8 7" />
    </g>
    <text x="320" y="314" class="ui-lead" text-anchor="middle">Select your image</text>
    <text x="320" y="344" class="ui-sub" text-anchor="middle">Add your photo or use an Avatar</text>

    <rect x="152" y="382" width="152" height="52" rx="13" class="ui-dash" stroke-dasharray="none" />
    <g class="ui-stroke" transform="translate(176 398)">
      <path d="M0 3a2 2 0 0 1 2-2h5l2 3h7a2 2 0 0 1 2 2v10a2 2 0 0 1-2 2H2a2 2 0 0 1-2-2z" />
    </g>
    <text x="208" y="414" class="ui-btn">Select</text>

    <rect x="336" y="382" width="152" height="52" rx="13" class="ui-dash" stroke-dasharray="none" />
    <g class="ui-stroke" transform="translate(360 398)">
      <circle cx="9" cy="6" r="5" /><path d="M0 20a9 9 0 0 1 18 0" />
    </g>
    <text x="392" y="414" class="ui-btn">Avatar</text>

    <rect x="28" y="478" width="584" height="64" rx="16" class="ui-dash" />
    <g class="ui-stroke" transform="translate(228 498)">
      <rect x="5" y="0" width="11" height="17" rx="5.5" />
      <path d="M0 13a10.5 10.5 0 0 0 21 0M10.5 23.5V28" />
    </g>
    <text x="268" y="517" class="ui-btn">Voice: choose one</text>
  </g>
</svg>
<p><span class="post-loop-caption">Two routes out of the same panel. The ring runs along the ready-made avatars and settles on the plus, which is the one you want if the face is going to be yours.</span></p>

<p>The single biggest factor in how good your avatar looks is the photo you hand it. High resolution, good lighting, face clearly visible, sharp focus. The better the input, the better the avatar, and no setting later in the process makes up for a soft photo at the start.</p>

<p><strong>Got a photo you love that is low quality?</strong> Open a project in MITO, run the image through one of the image models to upscale it, download the result, then upload that to Avatar Studio. The <a href="https://mito.ai/models/?type=image">image model guide</a> breaks down what each one is good at.</p>

<hr />

<h2 id="step-3-name-it-and-create">Step 3: Name it and create</h2>

<p>Give the avatar a name, ours is <strong>Josh 2.0</strong>, and click create.</p>

<p>MITO then studies the image and builds the things that make a face read as human on camera: blinking, eye movement, mouth shapes. It takes a moment. Once it is done, it needs a voice.</p>

<hr />

<h2 id="step-4-give-it-a-voice-or-clone-your-own">Step 4: Give it a voice, or clone your own</h2>

<p><strong>Option A: use the voice library.</strong> A big selection across accents, male and female, different speaking styles. Hit <strong>Play Sample</strong> on the right to preview any of them before committing.</p>

<p><strong>Option B: clone your own voice.</strong> If the avatar is you, it should sound like you.</p>

<ol>
  <li>Click <strong>Voice</strong>, then <strong>My Voices</strong>.</li>
  <li>Click <strong>Create Voice</strong> at the top and choose <strong>Clone a New Voice</strong>.</li>
  <li>Hit <strong>Start Recording</strong>. If you do not know what to say, there is a script at the bottom of the panel you can read.</li>
  <li>Once the voice is created, attach it to your avatar.</li>
</ol>

<p><strong>You need at least 20 seconds of audio.</strong> That is a lower bar than most voice tools ask for, and it is worth knowing you can record more than once. Giving it more of your range gets the clone closer to how you actually sound.</p>

<hr />

<h2 id="step-5-write-your-script-and-pick-settings">Step 5: Write your script and pick settings</h2>

<p>Now write what your clone is going to say. For the video, we typed in the exact line you read at the top of this post, which means the tutorial generates its own intro.</p>

<p>Two settings to check before you generate:</p>

<ul>
  <li><strong>Resolution.</strong> If you are testing, choose 720p over 1080p. It renders faster, so you find out whether you like the result before committing to a full-quality version.</li>
  <li><strong>Aspect ratio.</strong> 16:9 for horizontal YouTube. 9:16 for Shorts, Reels and TikTok.</li>
</ul>

<hr />

<h2 id="step-6-generate-preview-download">Step 6: Generate, preview, download</h2>

<p>Hit <strong>Generate</strong>. Longer scripts take longer, so timing depends on how much you wrote.</p>

<p>When it is ready, click play to preview. Happy with it? <strong>Download</strong> in the top right gives you an MP4, ready to post.</p>

<hr />

<h2 id="level-up-lip-sync-your-avatar-to-your-real-voice">Level up: lip-sync your avatar to your real voice</h2>

<p>Here is the honest bit about voice cloning: sometimes it does not sound exactly like you. Close, but a little off.</p>

<p>So skip the clone. Use your actual voice and have the avatar lip-sync to it.</p>

<p><strong>Option A: record in MITO.</strong> Where you would normally type a script, switch the input from text to audio, then record yourself saying whatever you want the avatar to say. MITO dubs that recording onto your avatar and lip-syncs it, so the mouth matches your real voice word for word.</p>

<p><strong>Option B: upload a file.</strong> Already have a recording? Upload it instead. Any common audio or video file works, so a clip you already shot is a valid source for the audio. Then hit <strong>Generate</strong>.</p>

<p>The result is your real voice coming out of your AI face. The only synthetic part left is the picture.</p>

<hr />

<h2 id="which-method-should-you-use">Which method should you use?</h2>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Typed script, cloned voice</th>
      <th>Your recording, lip-synced</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Speed</strong></td>
      <td>Fastest</td>
      <td>Slower, you have to record</td>
    </tr>
    <tr>
      <td><strong>Realism</strong></td>
      <td>Close, occasionally off</td>
      <td>Your actual voice</td>
    </tr>
    <tr>
      <td><strong>Script changes</strong></td>
      <td>Retype and regenerate</td>
      <td>Re-record</td>
    </tr>
    <tr>
      <td><strong>Best for</strong></td>
      <td>High volume, fast iteration</td>
      <td>When it really has to sound like you</td>
    </tr>
  </tbody>
</table>

<p>If you are making a lot of videos and iterating on scripts, clone the voice. If the video has to sound like you, record yourself.</p>

<hr />

<h2 id="one-rule-worth-saying-out-loud">One rule worth saying out loud</h2>

<p>Clone yourself, or someone who has clearly agreed to it.</p>

<p>A face and a voice belong to the person they came from, and “the tool let me” has never been a defence. This is the one part of the workflow that has nothing to do with which buttons you press.</p>

<hr />

<p><strong>The short version.</strong> Pick a face, give it a voice, write a script, generate. And if you want it to sound exactly like you, record yourself and let the avatar lip-sync.</p>

<p>An avatar is one piece of a production rather than the whole thing. For how the models and platforms underneath all this fit together, see <a href="/blog/how-ai-video-works/">How AI Video Works</a>. For a full build from one idea to a finished, scored film, see <a href="/blog/how-to-make-an-ai-explainer-video/">How to Make an AI Explainer Video, Start to Finish</a>.</p>

<p><a href="https://app.mito.ai/">Try Avatar Studio in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[One photo, 20 seconds of your voice, and a script. Build a talking AI clone of yourself in about five minutes, plus the trick that makes it sound like you.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/preview.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/how-to-make-an-ai-avatar-of-yourself/preview.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How AI Video Works: Models, Platforms, and One Real Build</title><link href="https://mito.ai/blog/how-ai-video-works/" rel="alternate" type="text/html" title="How AI Video Works: Models, Platforms, and One Real Build" /><published>2026-09-25T00:00:00+02:00</published><updated>2026-09-25T00:00:00+02:00</updated><id>https://mito.ai/blog/how-ai-video-works</id><content type="html" xml:base="https://mito.ai/blog/how-ai-video-works/"><![CDATA[<p>Everyone throws the term “AI video” around like it is one thing. It is not. It is two completely different layers stacked on top of each other, and once that clicks, the whole space makes a lot more sense.</p>

<p><strong>Layer one is the models</strong> actually generating footage. <strong>Layer two is the platforms</strong> built on top of them. Here is what each one does, plus a real example of what building something on that second layer looks like, start to finish.</p>

<hr />

<h2 id="layer-one-the-models">Layer one: the models</h2>

<p>This is the raw generation layer. Models like Kling and Seedance, turning a prompt directly into footage.</p>

<p>These are doing the actual heavy lifting, and they are not interchangeable. The same prompt run through two different models can come back with completely different motion, style and fidelity. Same words in, genuinely different films out.</p>

<p>Here is one prompt, run twice:</p>

<blockquote>
  <p>A Pixar-style animated sequence: A young girl sneaks out of her bedroom, slips on a superhero mask, and teams up with her talking orange cat. Together, they leap into action to stop a neighborhood wall graffitist.</p>
</blockquote>

<div class="post-gallery">
  <figure>
    <video controls="" playsinline="" preload="metadata" width="1280" height="720" poster="/blog/assets/posts/how-ai-video-works/poster-seedance.jpg" src="/blog/assets/posts/how-ai-video-works/vid-seedance.mp4"></video>
    <figcaption>
      <span class="media-label__name">Seedance 2.5</span>
      <span class="media-label__meta">1280x720 &middot; 16:9 &middot; 10s</span>
    </figcaption>
  </figure>
  <figure>
    <video controls="" playsinline="" preload="metadata" width="1280" height="720" poster="/blog/assets/posts/how-ai-video-works/poster-omni.jpg" src="/blog/assets/posts/how-ai-video-works/vid-omni.mp4"></video>
    <figcaption>
      <span class="media-label__name">Omni</span>
      <span class="media-label__meta">1280x720 &middot; 16:9 &middot; 10s</span>
    </figcaption>
  </figure>
</div>
<p><span class="post-loop-caption">The same prompt, the same settings, two models. Press play on each.</span></p>

<p>Identical settings on both sides. Everything that differs is the model’s own reading of the same sentence, and the two readings are not close.</p>

<p><strong>Seedance stays indoors, in daylight, and goes tight.</strong> A close-up on the girl’s face as the mask goes on, shallow focus, the cat a soft orange shape in the window behind her.</p>

<p><strong>Omni goes outside, at night, and goes wide.</strong> The girl mid-stride across a back garden, toys scattered in the grass, the cat watching from the fence. Both of them masked, which the prompt never actually asked for.</p>

<p>Neither one is wrong. The prompt never said where, or when, or how close to stand. That is the part worth sitting with: the model is making real directorial decisions in every gap you leave it, so which one you reach for is a creative choice with a visible result rather than a technical default. The <a href="https://mito.ai/models/?type=video">video model guide</a> breaks down what each tends to be good at.</p>

<p>Almost nobody talks to these models directly, though. That is what the second layer is for.</p>

<hr />

<h2 id="layer-two-the-platforms">Layer two: the platforms</h2>

<p>MITO, Runway, OpenArt, Higgsfield. These exist because access to raw models only gets you footage. It does not get you character consistency, more than one model to choose between, or an actual edit. All the things that turn “a generated clip” into “a finished video.”</p>

<p>MITO’s approach specifically is to make filmmaking and AI video production easier for creatives and teams: a collaborative canvas with a built-in assistant, <a href="/blog/introducing-director/">Director</a>, doing the heavy lifting. Instead of stitching together prompts, references and edits yourself, you describe what you want and it builds the production around that one idea.</p>

<hr />

<h2 id="building-one-live-from-one-sentence-to-a-finished-short-film">Building one, live: from one sentence to a finished short film</h2>

<p>Here is what that actually looks like. We opened a new project on MITO’s canvas and gave Director one sentence:</p>

<blockquote>
  <p>I want a 30 second, Pixar-styled short film, where a mischievous girl cuts a strand of her own hair and enjoys it, then keeps cutting until she’s bald. She’s in her bathroom and her cat is watching the whole thing.</p>
</blockquote>

<p>From that, Director wrote the script, built a production plan, and generated the character and location references it needed: the girl, the cat, the bathroom. Those references are what MITO calls Elements, the same mechanism covered in <a href="/blog/introducing-elements/">Keep the same character in every shot</a>. It added sound design and voiceover automatically, then dropped everything into a timeline we could edit directly.</p>

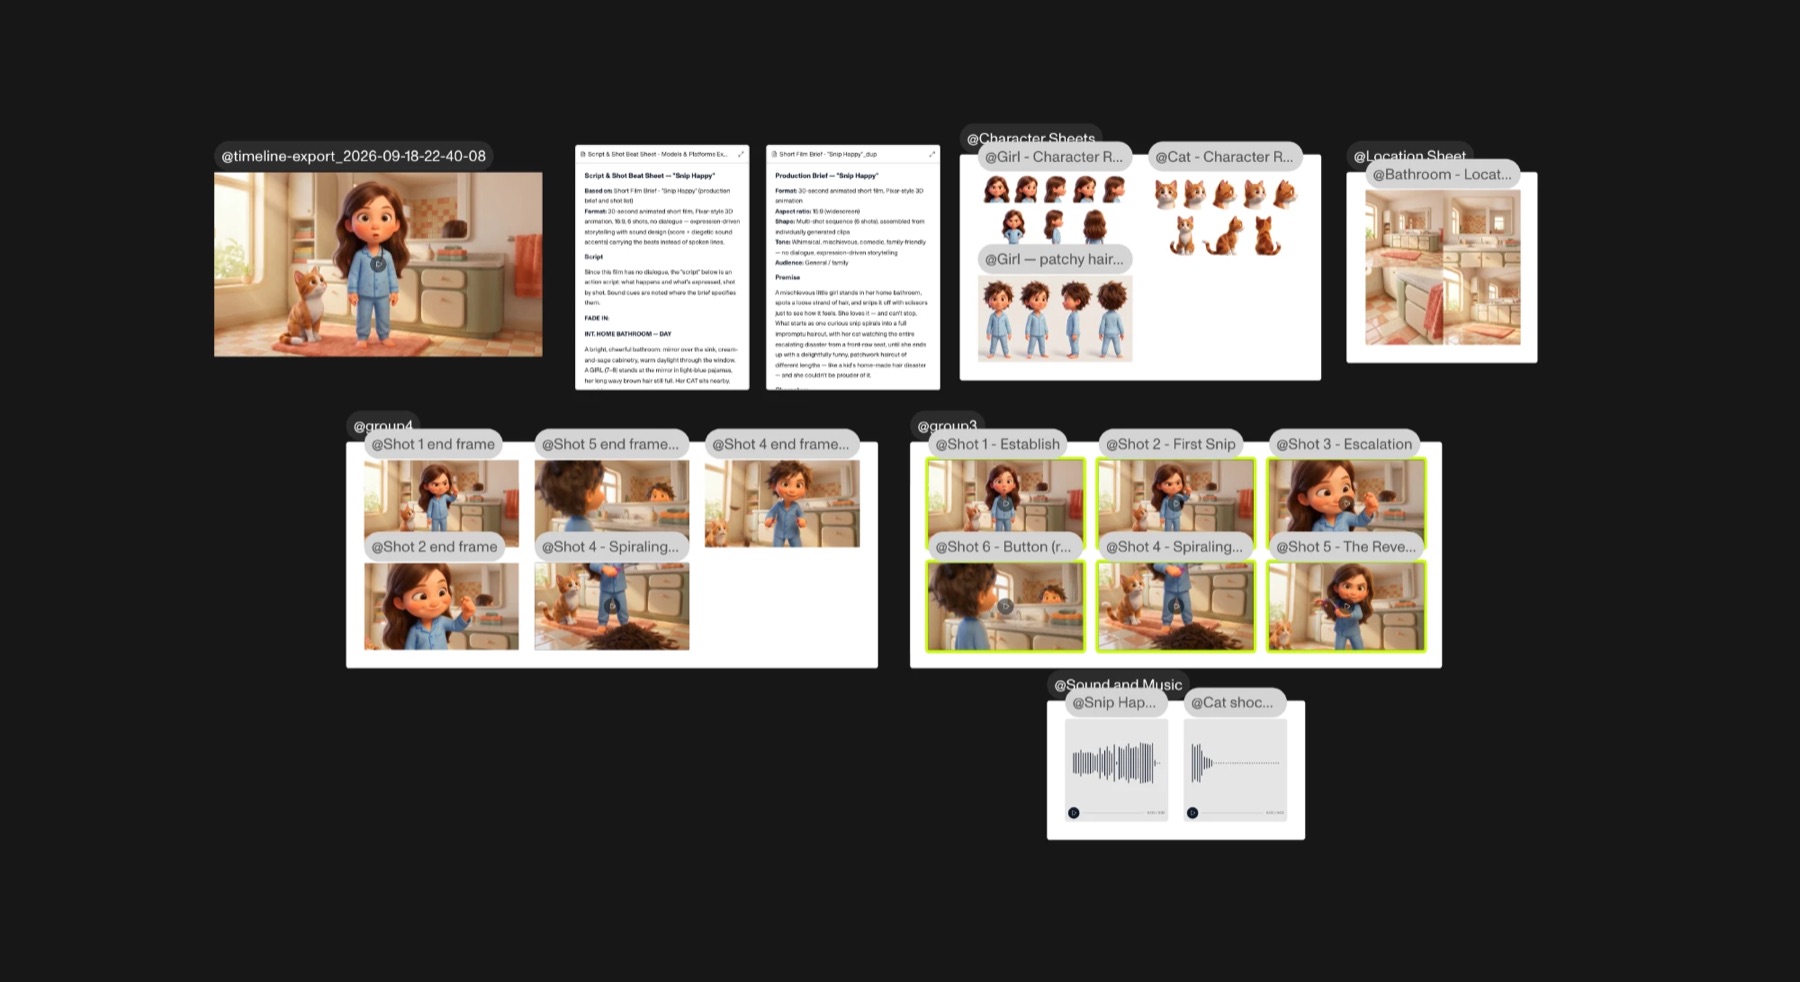
<p><img class="img-wide" src="/blog/assets/posts/how-ai-video-works/canvas-build.jpg" loading="lazy" width="2000" height="1092" alt="The MITO canvas after Director built the film: a timeline export, a script and shot beat sheet, character sheets for the girl and the cat, a bathroom location sheet, grouped cards for all six shots, and a sound and music group" />
<span class="post-loop-caption">Everything above came from that one sentence: the beat sheet, the character and location sheets, six shots grouped as key frames and clips, and the sound and music.</span></p>

<p><strong>Total time, with a counter running on screen the whole way: about four minutes.</strong> One sentence in, a full short film out.</p>

<p>This example is deliberately quick, and that is the point of it. For the full step-by-step version, including locking references into Elements before you generate anything, catching continuity drift at the key frame instead of the video, and scoring the final cut, see <a href="/blog/how-to-make-an-ai-explainer-video/">How to Make an AI Explainer Video, Start to Finish</a>.</p>

<hr />

<p><strong>The short version.</strong> Models generate the footage. Platforms turn that into something usable. Director turns one idea into a finished production, start to finish.</p>

<p>The distinction matters more than it sounds like it should. Most of the confusion about what AI video can and cannot do yet comes from judging the whole space by one layer of it.</p>

<p><a href="https://app.mito.ai/">Open MITO and try one sentence →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[AI video is two layers: the models generating the footage, and the platforms built on top. What each one does, plus a short film built from one sentence.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/how-ai-video-works/preview.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/how-ai-video-works/preview.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to Make an AI Explainer Video, Start to Finish</title><link href="https://mito.ai/blog/how-to-make-an-ai-explainer-video/" rel="alternate" type="text/html" title="How to Make an AI Explainer Video, Start to Finish" /><published>2026-09-24T00:00:00+02:00</published><updated>2026-09-24T00:00:00+02:00</updated><id>https://mito.ai/blog/how-to-make-an-ai-explainer-video</id><content type="html" xml:base="https://mito.ai/blog/how-to-make-an-ai-explainer-video/"><![CDATA[<p>Explainer videos work because they take something you would normally have to read and turn into something you just watch. That is the whole appeal, and it is exactly the kind of project MITO is built for: one idea, a handful of generated scenes, a voiceover and a score, all inside the same canvas.</p>

<p>Here is the walkthrough we used to build a real one. A 30-second, stop-motion-style explainer on the invention of the elevator, from the first prompt to the final export.</p>

<hr />

<h2 id="start-with-a-story-people-already-half-know">Start with a story people already half-know</h2>

<p>The idea does not need to be complicated. It needs a hook someone already has a foothold in. Ours: the Otis elevators sitting in half the apartment buildings in San Francisco. Most people have ridden one and never wondered where it came from, so “here is how that got invented” does the work for you before you have written a single scene.</p>

<p>Once the idea is set, describe the whole thing to <a href="/blog/introducing-director/">Director</a> in one message. The topic, the visual style (construction paper, stop-motion, tear noises and sound effects, 3D objects and characters), and one instruction that matters more than it sounds like it should: every scene has to flow seamlessly into the next.</p>

<p>That last part is not a style note. Video generations run on key frames, the start, end or in-between images a scene is built from, so asking for seamless scene-to-scene transitions up front is what makes six separate generations read as one continuous film instead of six disconnected clips. If key frames are new to you, <a href="/blog/what-is-a-start-frame-in-ai-video/">start here</a>.</p>

<hr />

<h2 id="let-director-ask-you-the-questions-first">Let Director ask you the questions first</h2>

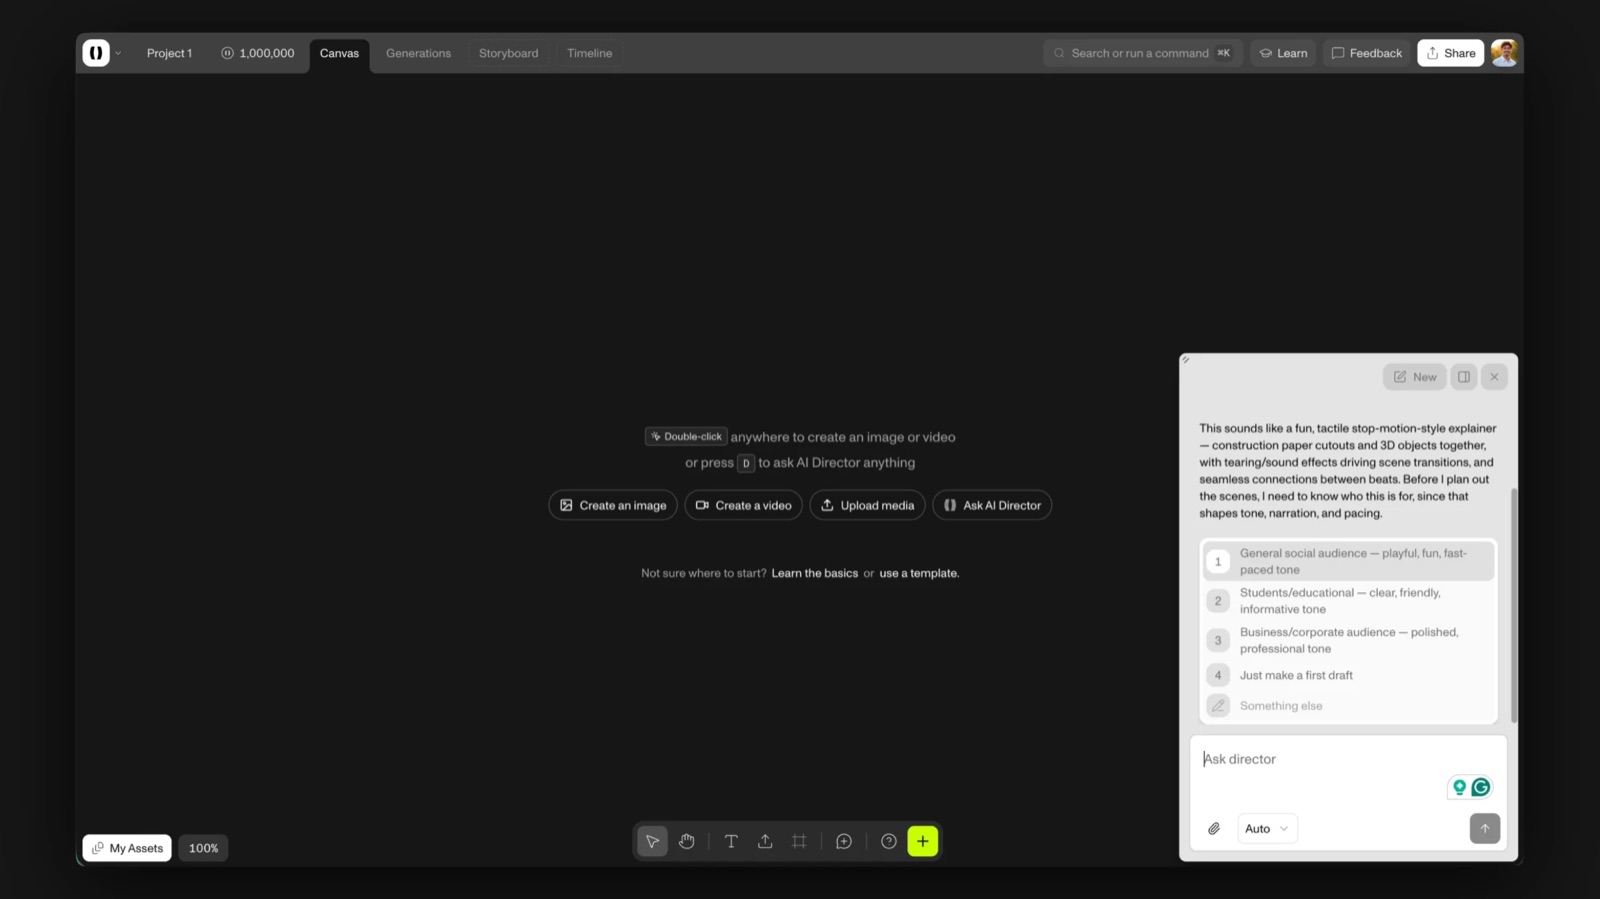
<p>Before it builds anything, Director asks who the video is actually for and what format it needs. That is worth answering deliberately rather than skipping past.</p>

<p>Broad, top-of-funnel content plays differently than something built for a classroom. And 16:9 horizontal is the right call for YouTube even though vertical technically performs better on TikTok. Answer both up front and the tone and shape of everything Director generates after this lines up with what you actually meant.</p>

<p><img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/director-brief.jpg" alt="Director asking a clarifying question in the MITO canvas, offering a numbered list of audience options: general social, students, business, or just make a first draft" /></p>

<hr />

<h2 id="lock-your-references-into-elements-before-you-generate-anything">Lock your references into Elements before you generate anything</h2>

<p>Once Director has a brief and a shot plan, the next move is not to jump into video. It is to build out Elements: a Character element for the tinkerer, and separate references for the elevator across its three eras.</p>

<p>Elements are what MITO uses to hold identity and continuity across shots. Define one once, then @mention it in every scene prompt after that instead of re-describing the same character or object every time.</p>

<p>Skip this and you will notice it later. The character starts drifting, an outfit changes shade, a face reads slightly off by shot four. Building the Element up front is the fix, not a cleanup step after the fact. More on how they work in <a href="/blog/introducing-elements/">Keep the same character in every shot</a>.</p>

<div class="post-gallery">
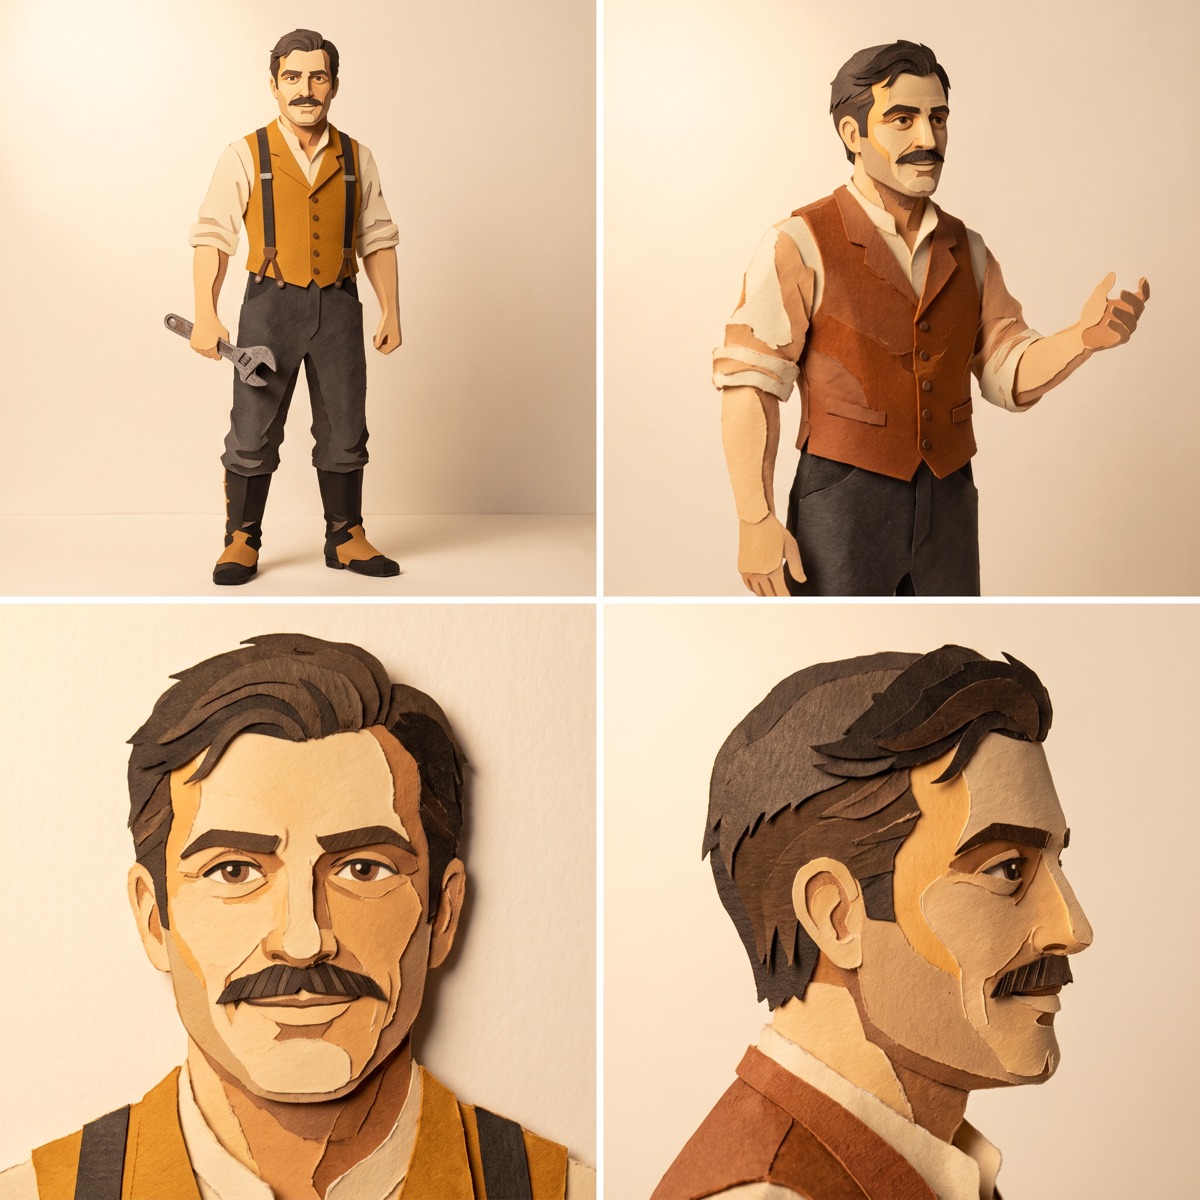
  <img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/character-reference.jpg" loading="lazy" width="1200" height="1200" alt="Character reference sheet for the inventor, built from layered construction paper: full body with a wrench, a three-quarter turn, and front and profile face close-ups" />
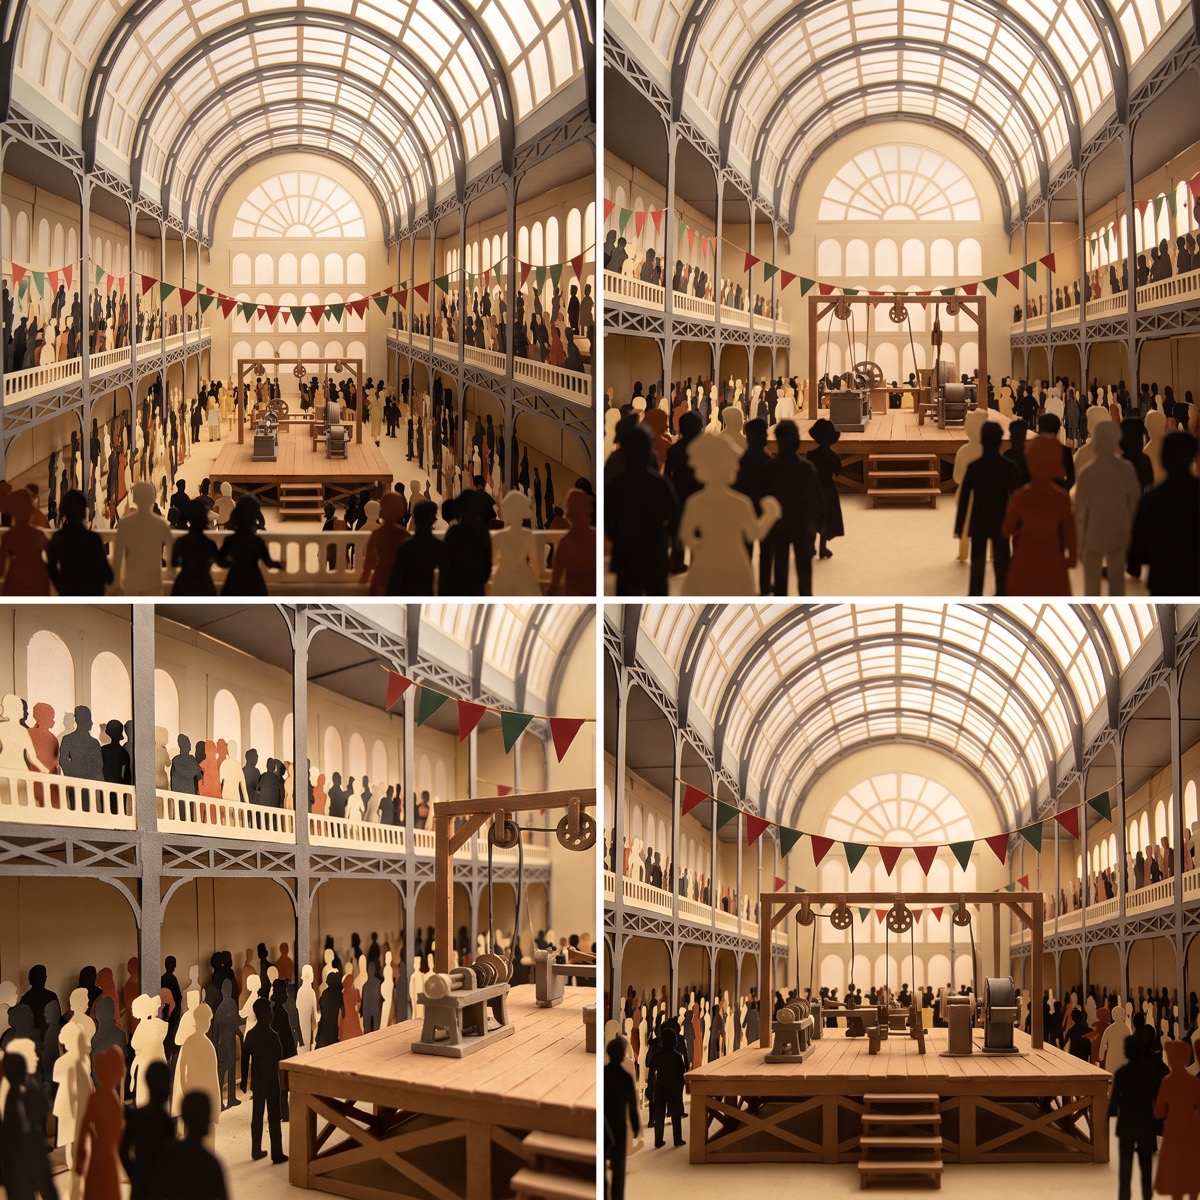
  <img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/location-reference.jpg" loading="lazy" width="1200" height="1200" alt="Location reference sheet for the exhibition hall, four angles of a paper-cutout glass-roofed Victorian hall with a crowd and a demonstration platform" />
</div>
<p><span class="post-loop-caption">Two of the Elements: the inventor and the exhibition hall, each built across several angles so the model has something to hold on to from any shot.</span></p>

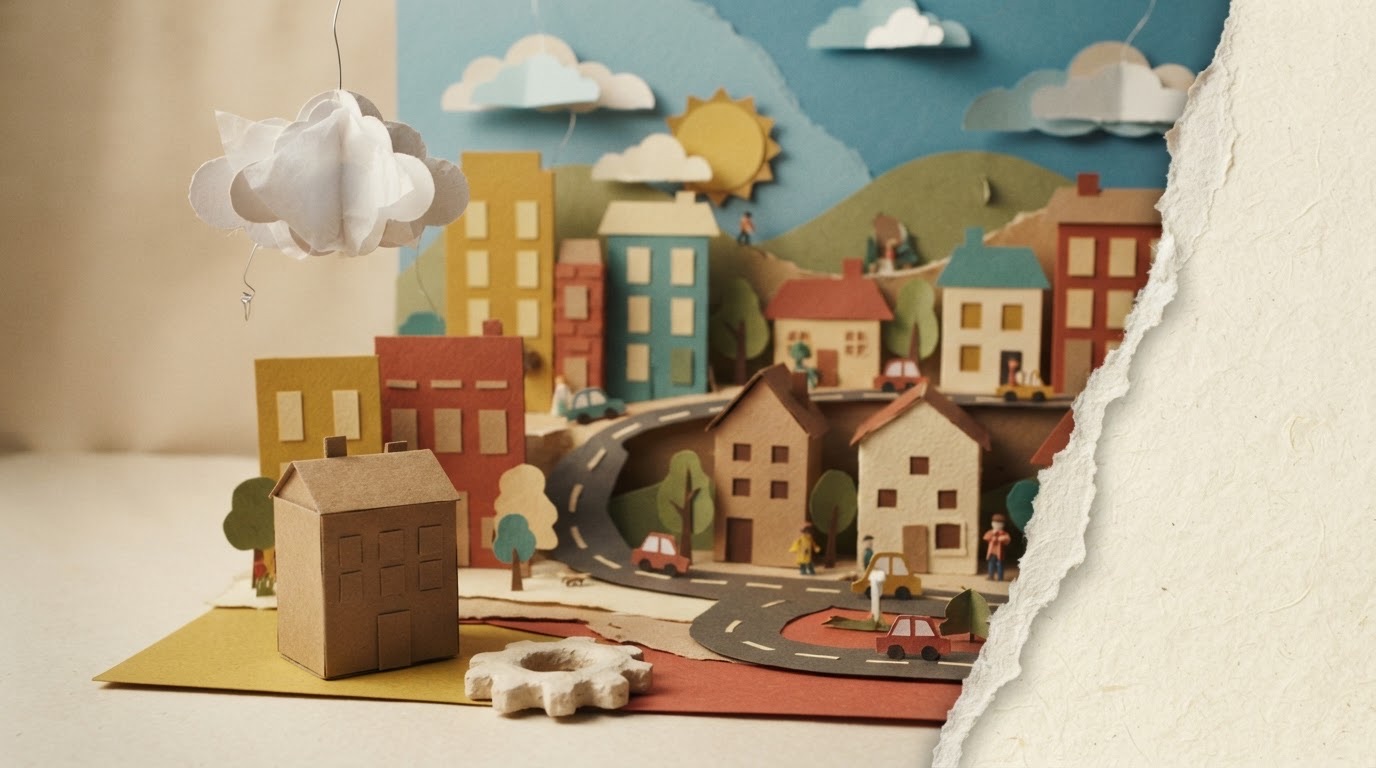
<p>The style reference does the same job for the look of the film rather than for anything in it.</p>

<p><img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/style-reference.jpg" alt="Style reference for the film: a construction paper town with layered card buildings, a winding road, paper clouds on wires and a torn paper edge at the frame" /></p>

<hr />

<h2 id="one-idea-becomes-six-key-frames">One idea becomes six key frames</h2>

<p>With Elements set, the shot plan turns into actual images: one key frame per scene. Six scenes, six key frames, each one @mentioning the right Elements so the character and the elevator read consistently frame to frame.</p>

<p>Two workspace habits worth keeping while these generate. <strong>Shift+A</strong> auto-aligns whatever you have selected on the canvas, and <strong>Shift+G</strong> groups it into a labeled box, so your references do not turn into visual noise by scene four.</p>

<p>And worth knowing if you are counting credits: talking to Director costs nothing. Asking it questions, getting a second opinion on a shot, having it explain a step, none of that spends credits. Only the generations do.</p>

<hr />

<h2 id="catch-continuity-errors-at-the-key-frame-not-the-video">Catch continuity errors at the key frame, not the video</h2>

<p>Watch every generated clip on its own before moving on, not just the whole sequence back to back. Two things slipped through on this build, and both were caught the same way.</p>

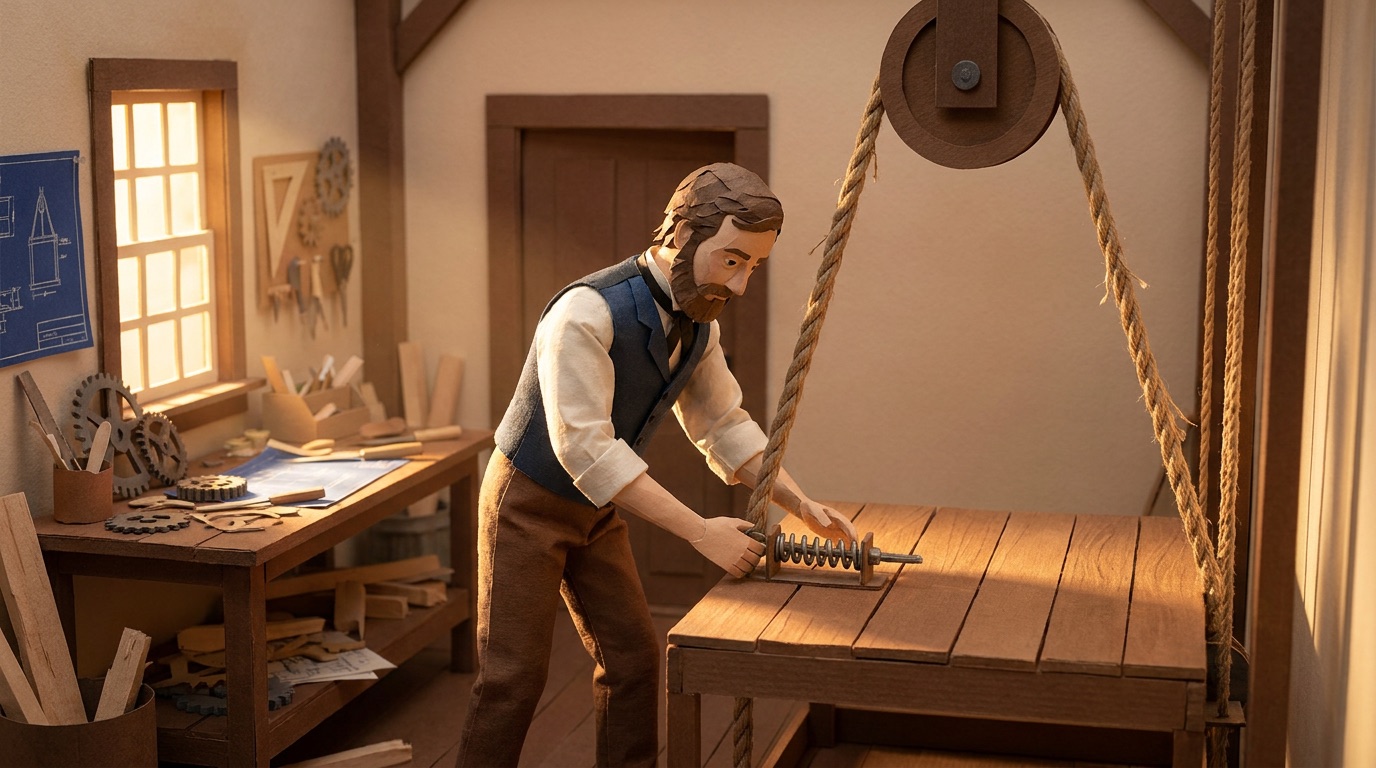
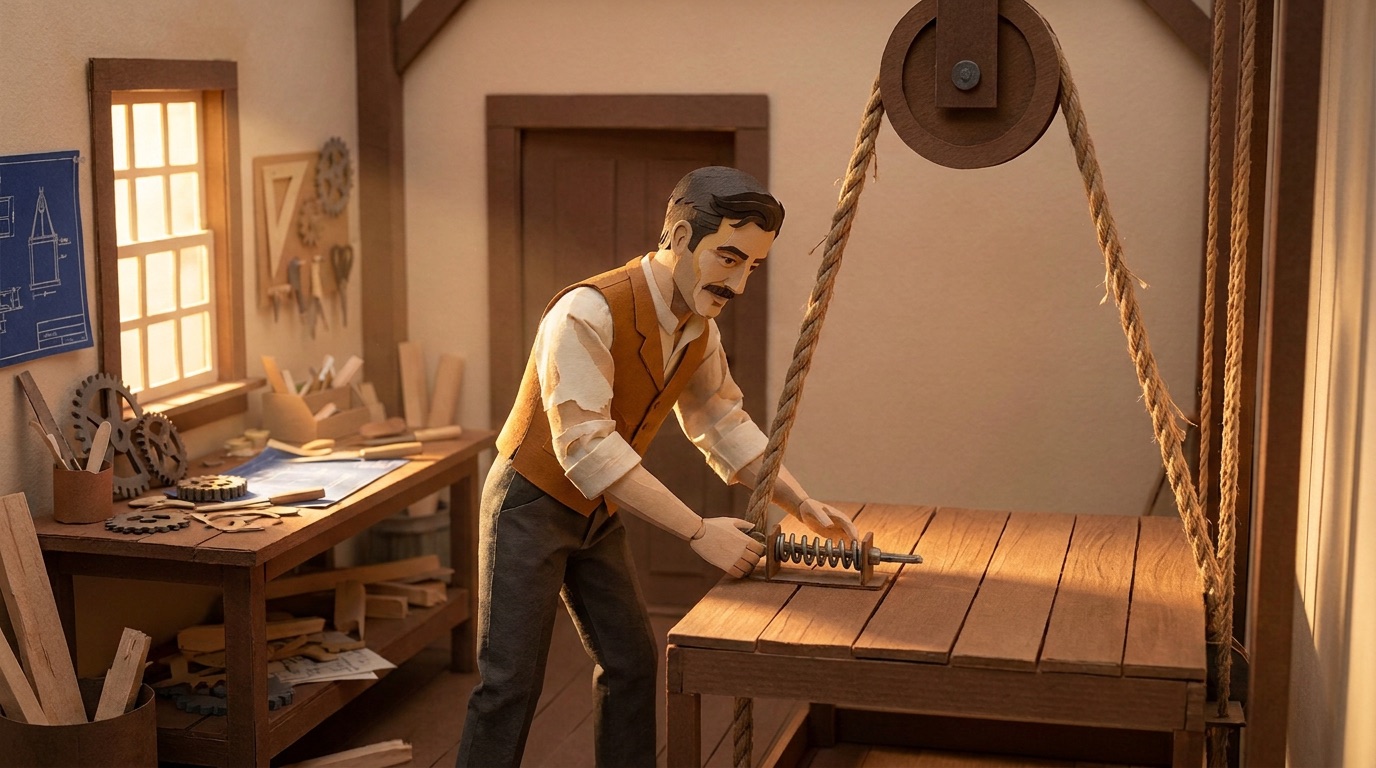
<p><strong>The character drifted.</strong> Scene two came back with a full beard, a blue vest and brown trousers, when the Element has a moustache, a rust vest and grey trousers. Nothing in the shot is wrong exactly, it is just not the same man who appears in the scene before it.</p>

<div class="frame-pair frame-pair--wide">
  <figure class="frame-pair__item frame-pair__item--source">
    <figcaption class="frame-pair__label">Drifted</figcaption>
    <img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/scene-2-character-drift.jpg" loading="lazy" width="1376" height="768" alt="Scene two key frame with the character off model: full beard, blue vest and brown trousers" />
  </figure>
  <div class="frame-pair__arrow" aria-hidden="true"></div>
  <figure class="frame-pair__item frame-pair__item--result">
    <figcaption class="frame-pair__label">Back on model</figcaption>
    <img src="/blog/assets/posts/how-to-make-an-ai-explainer-video/scene-2-on-model.jpg" loading="lazy" width="1376" height="768" alt="The same scene two key frame corrected to match the Character element: moustache, rust vest and grey trousers" />
  </figure>
</div>
<p><span class="post-loop-caption">Same room, same staging, same spring on the bench. The only thing that moved is the man, which is exactly the kind of drift a Character element exists to stop.</span></p>

<p><strong>And a rope broke early.</strong> One scene had a rope that was already snapped in the key frame, but the generated video showed it still trembling, as though the break had not happened yet. Small thing, and it reads as “off” even to someone who cannot say why.</p>

<p>The fix in both cases is the same, and it is not to regenerate the video and hope. Go back to the key frame, correct it there, then regenerate the clip from the corrected frame. The video is only ever as accurate as the frame it came from.</p>

<p>That is also the cheapest place to fix it. A wrong key frame costs one image to redo. A wrong video costs the video.</p>

<hr />

<h2 id="one-prompt-to-score-it-one-prompt-to-trim-it">One prompt to score it, one prompt to trim it</h2>

<p>With every scene generated and the continuity fixes in place, open a second Director chat and ask it for a voiceover that sits on top of the video and carries the story across every scene. Naming the chat something like “VO” keeps your workspace legible. You do not need clean grammar in the request either, Director works from what you mean.</p>

<p>Once the voiceover is in, assemble the clips on the timeline. It behaves like any editing software: video, audio, images, text and transitions on tracks, with position, rotation and speed adjustable per clip.</p>

<p>From there, one Director message can do double duty. Score the whole thing with music and add the voiceover on top, in the same request rather than two separate ones. If the pacing feels off on playback, say so directly. Faster, more exciting, trimmed under the length you need. Let Director make the pass instead of re-cutting by hand.</p>

<hr />

<h2 id="what-it-cost">What it cost</h2>

<p>The full build, six generated scenes, one continuity fix, a voiceover and a score, came to about <strong>6,200 credits</strong> and roughly <strong>30 minutes</strong>, most of which was waiting on generations rather than working.</p>

<p>Worth saying where the cost actually sits: regenerations. Every shortcut taken before the Elements were built came back later as a scene that needed running twice. Getting the references right first is the cheapest thing in this whole workflow.</p>

<p>Not sure which model to reach for at each stage? The <a href="https://mito.ai/models/?type=video">video model guide</a> breaks down what each one is good at.</p>

<hr />

<p><strong>The short version.</strong> A hook worth explaining. Elements locked in before you generate. Key frames checked before the video is. And one honest fix along the way when a step gets missed.</p>

<p>None of that requires the story to be complicated. It just requires the workflow to hold together, and that part is on the tool.</p>

<p>Want to watch the whole thing being built? The full walkthrough is at the top of this post, and on <a href="https://youtu.be/Fe7F8oXPh7I">our YouTube channel</a>.</p>

<p>Keeping a character steady across a whole sequence is the piece most people lose first. The full method is in <a href="/blog/how-to-keep-ai-video-characters-consistent/">How to Keep AI Video Characters Consistent</a>.</p>

<p><a href="https://app.mito.ai/">Build your first explainer in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[One idea, one Director chat, six generated scenes. The exact workflow we used to build a 30-second stop-motion explainer inside MITO, start to finish.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/how-to-make-an-ai-explainer-video/preview.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/how-to-make-an-ai-explainer-video/preview.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">What Is a Start Frame in AI Video Generation?</title><link href="https://mito.ai/blog/what-is-a-start-frame-in-ai-video/" rel="alternate" type="text/html" title="What Is a Start Frame in AI Video Generation?" /><published>2026-09-23T00:00:00+02:00</published><updated>2026-09-23T00:00:00+02:00</updated><id>https://mito.ai/blog/what-is-a-start-frame-in-ai-video</id><content type="html" xml:base="https://mito.ai/blog/what-is-a-start-frame-in-ai-video/"><![CDATA[<p>If you have opened any AI video tool, you have seen a field labelled “start frame”, “first frame” or “reference image”. You have probably skipped it, or thrown in a random photo and hoped.</p>

<p>Here is what it actually does, and why it is one of the highest-leverage controls you have.</p>

<hr />

<h2 id="a-video-is-just-a-sequence-of-images">A video is just a sequence of images</h2>

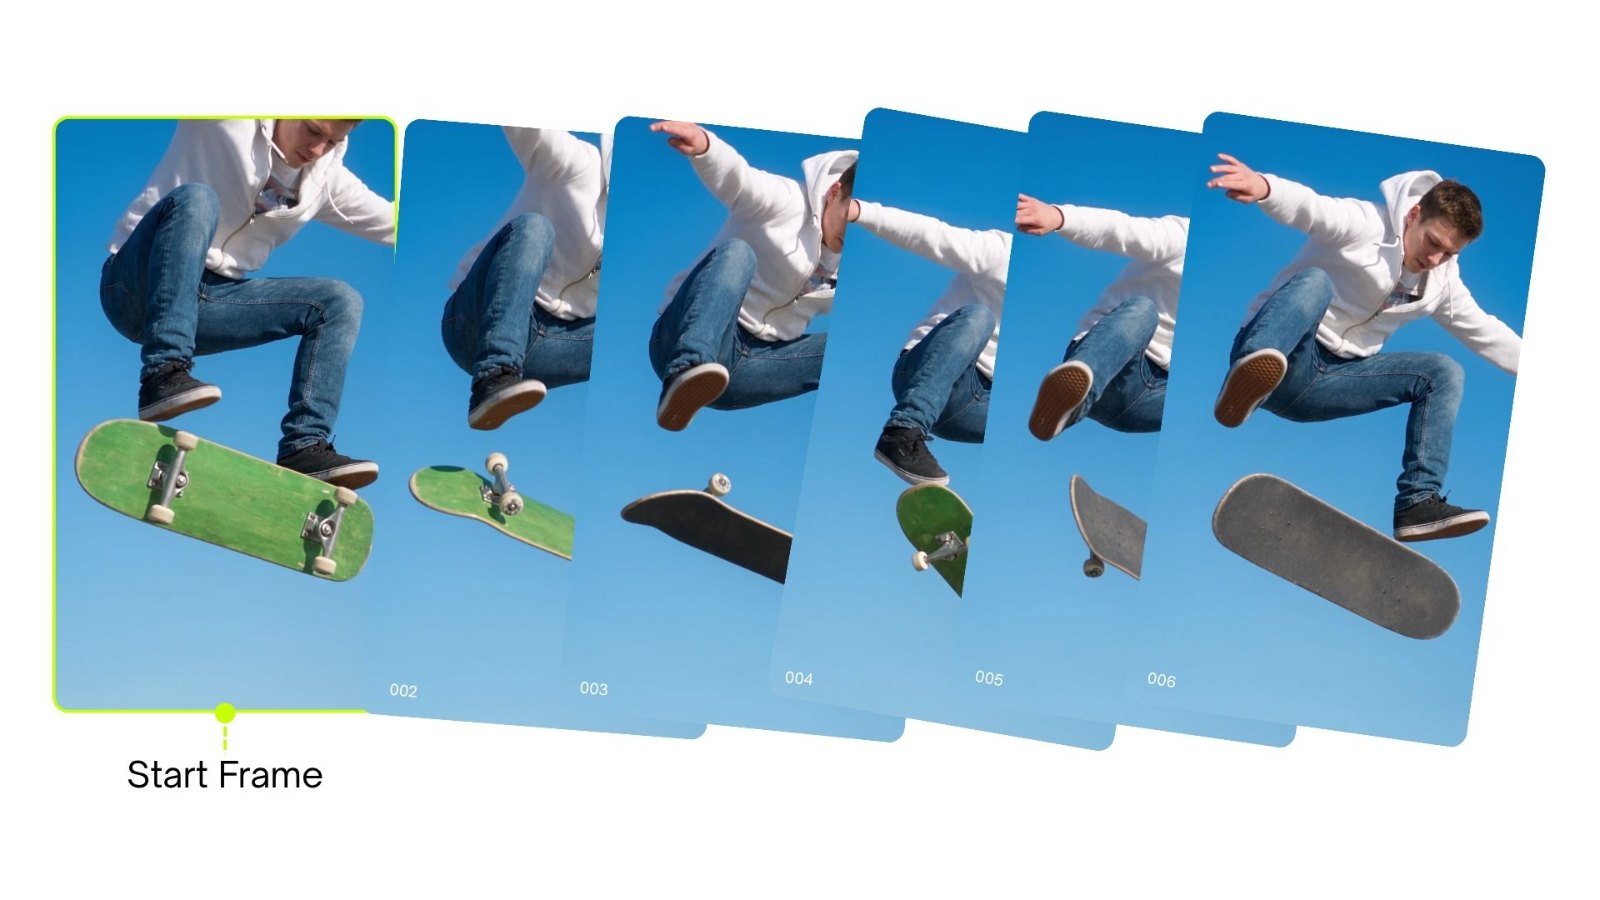
<p>A video is a run of still images shown one after another, fast enough to read as motion. That is what fps means: frames per second. A start frame is simply the first image in that sequence, the fixed point everything after it evolves from.</p>

<p>Type a prompt with nothing else and the model has nothing to anchor to, so it invents its own start frame from whatever it thinks fits your description. Give it a real one and it skips that guesswork entirely. It is no longer imagining where the shot begins, only working out what happens after.</p>

<p><img src="/blog/assets/posts/what-is-a-start-frame/img-01.jpg" alt="A strip of still frames laid out in sequence, showing how a video is a run of individual images played fast enough to read as motion" /></p>

<hr />

<h2 id="a-real-comparison">A real comparison</h2>

<p>Say you want a character, call him Jeff, landing a skateboard trick.</p>

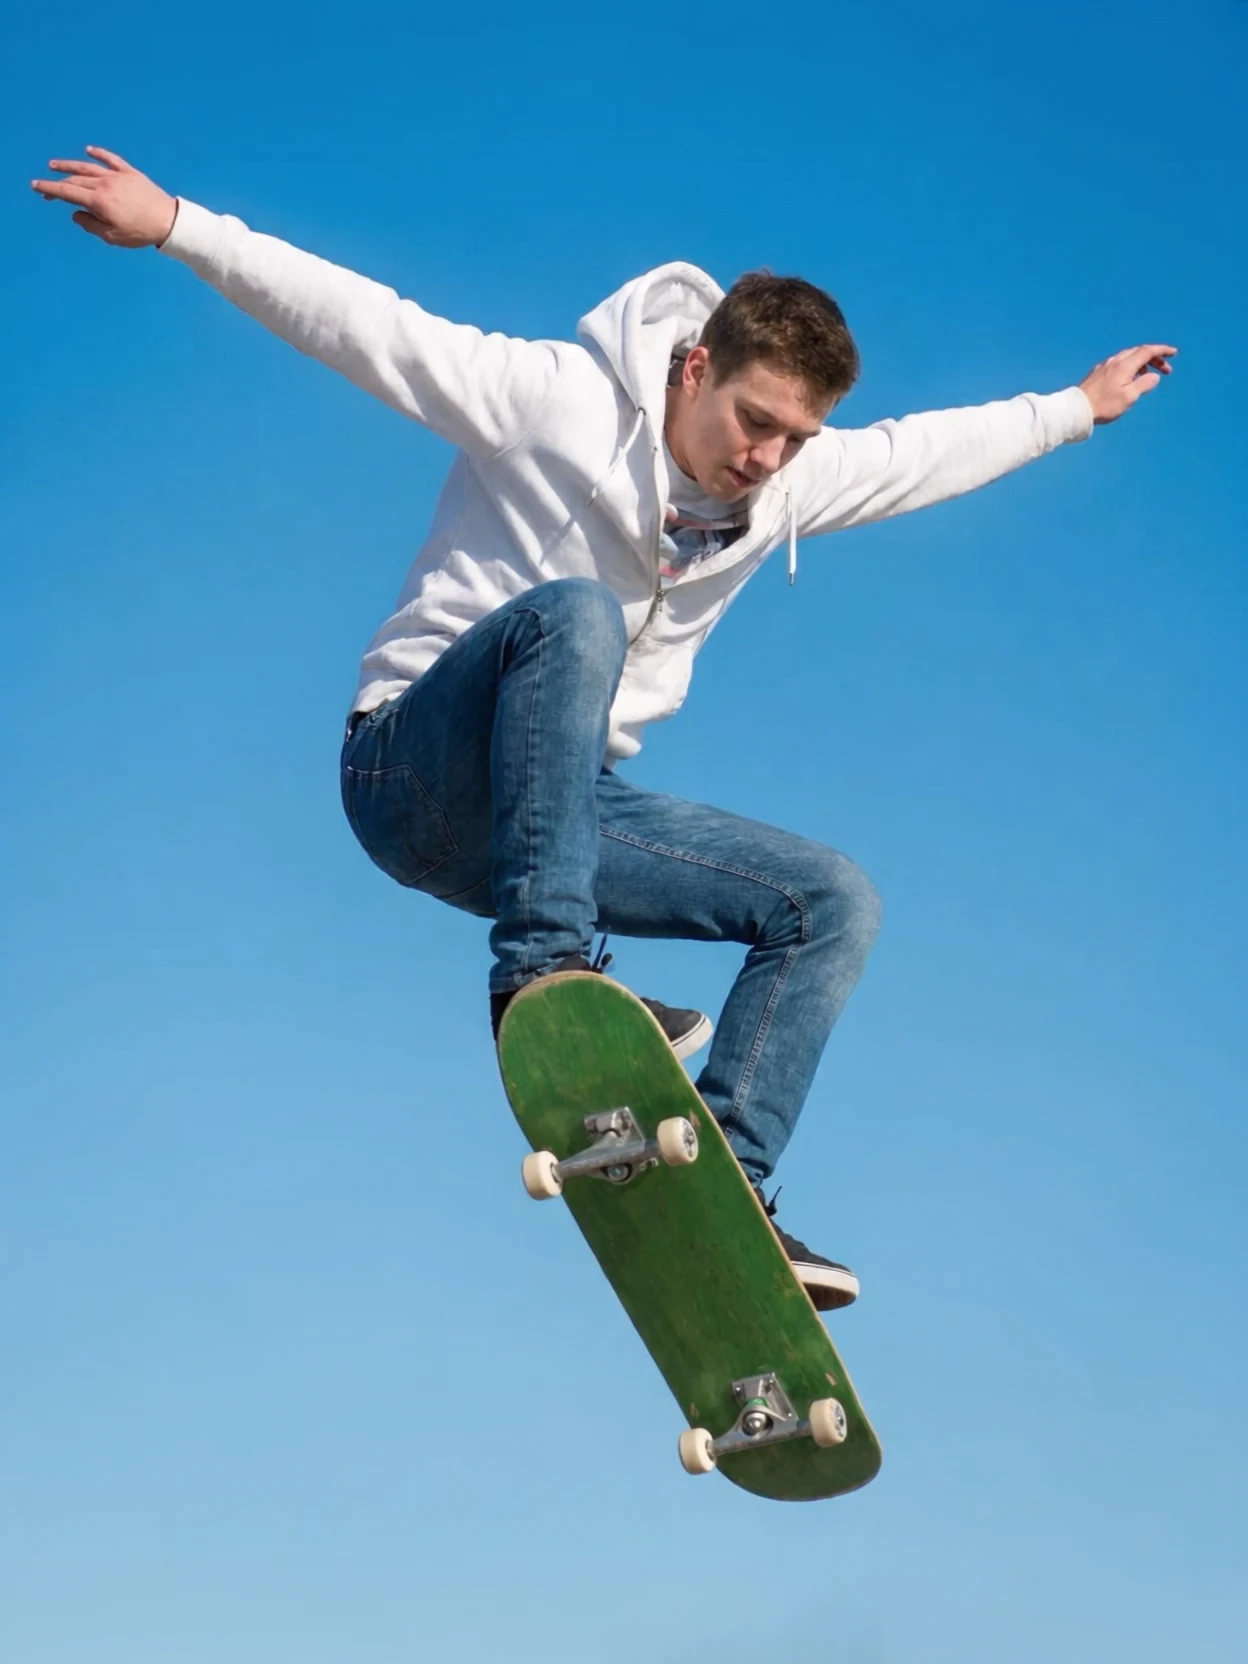
<p><strong>Without a start frame</strong>, you write the prompt and the model decides where the shot opens. You might get him rolling up to the ramp. You might get him already in the air. It is a coin flip, and you find out after the generation has run.</p>

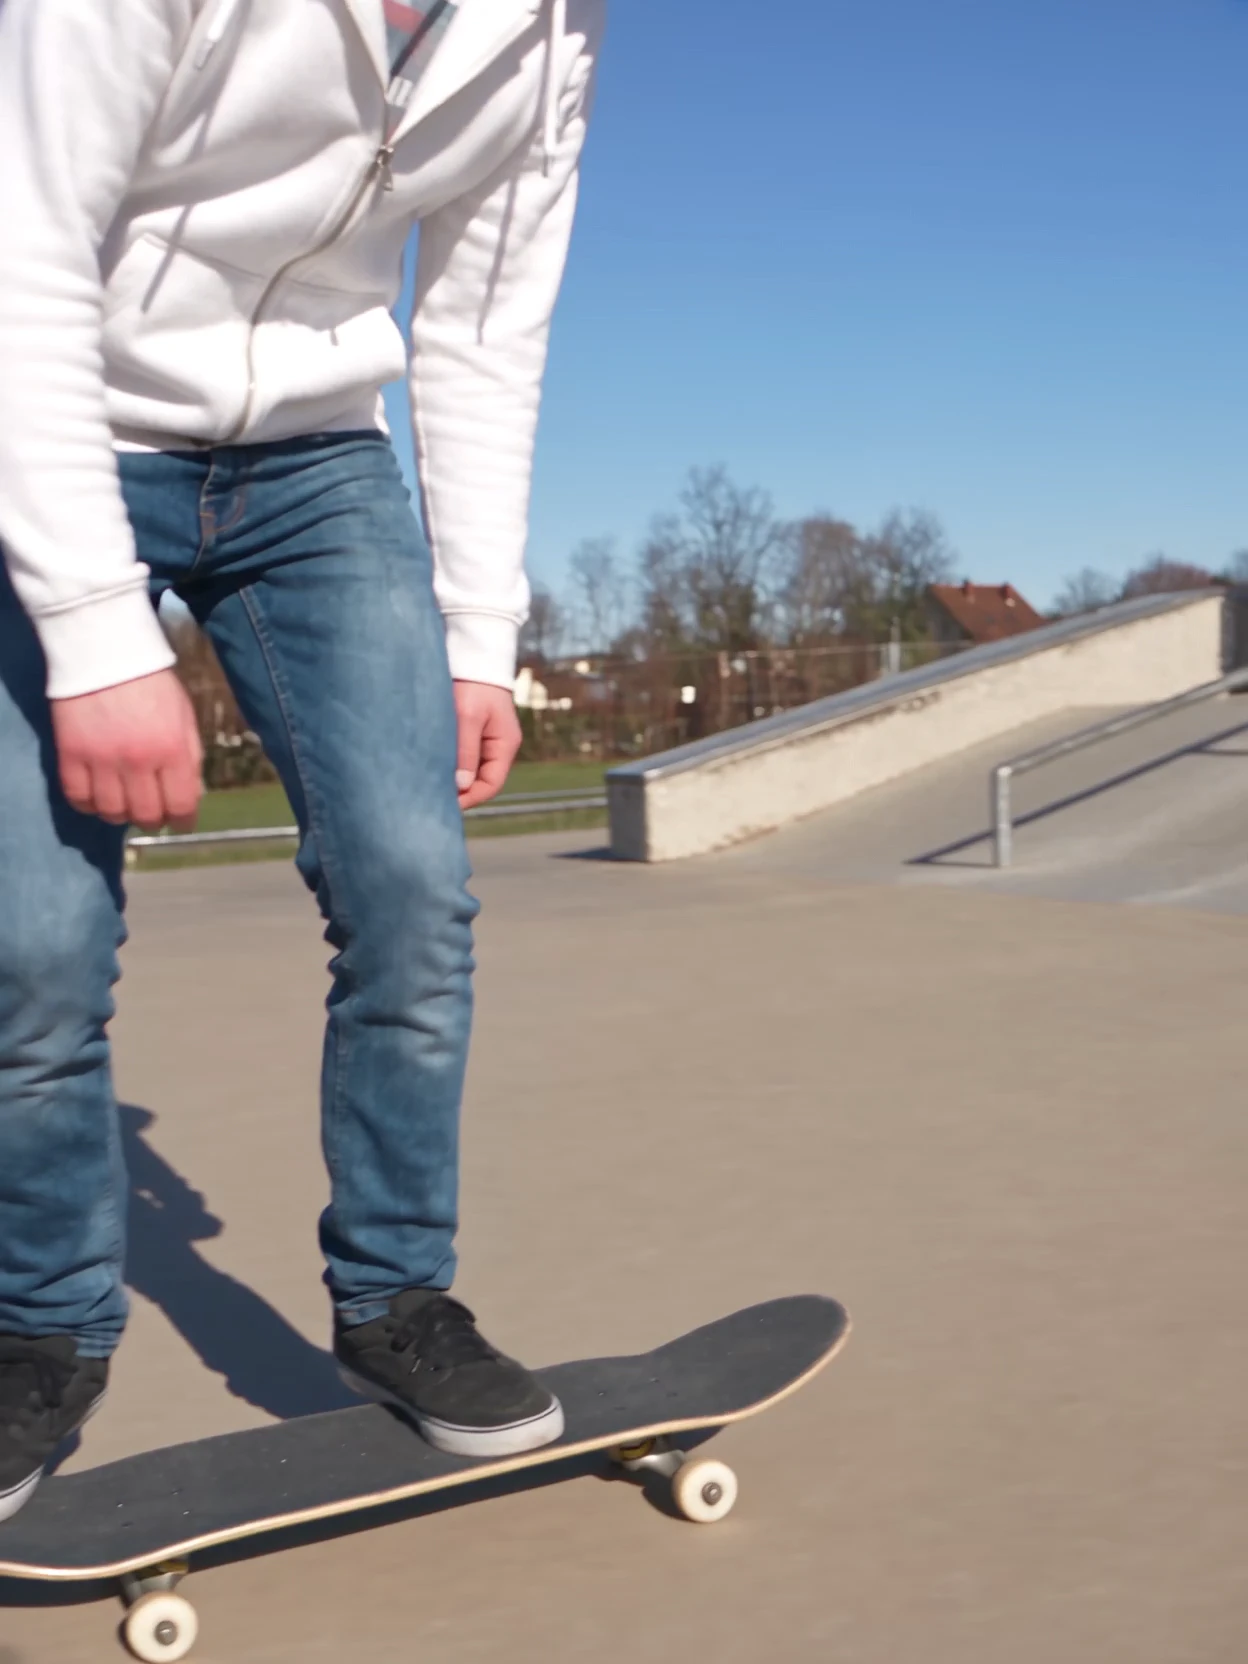
<p><strong>With a start frame</strong>, you decide. Below are two we made, and the clips each one produced. Same prompt, same settings (Seedance 2.5, 1080p, 3:4, 8 seconds). The only thing that changed between them is the image handed in first.</p>

<div class="frame-pair">
  <figure class="frame-pair__item frame-pair__item--source">
    <figcaption class="frame-pair__label">Start frame</figcaption>
    <img src="/blog/assets/posts/what-is-a-start-frame/img-02.webp" width="1248" height="1664" loading="lazy" alt="Start frame: Jeff mid-air against a clear blue sky, the green board flipped under his feet, arms out for balance" />
  </figure>
  <div class="frame-pair__arrow" aria-hidden="true"></div>
  <figure class="frame-pair__item frame-pair__item--result">
    <figcaption class="frame-pair__label">The clip it produced</figcaption>
    <video controls="" playsinline="" preload="metadata" width="1248" height="1664" poster="/blog/assets/posts/what-is-a-start-frame/img-02.webp" src="/blog/assets/posts/what-is-a-start-frame/vid-flip.mp4"></video>
  </figure>
</div>
<p><span class="post-loop-caption">Hand it the peak of the trick and the clip opens there, already airborne, and plays out the landing. Press play on the clip to watch the still move.</span></p>

<div class="frame-pair">
  <figure class="frame-pair__item frame-pair__item--source">
    <figcaption class="frame-pair__label">Start frame</figcaption>
    <img src="/blog/assets/posts/what-is-a-start-frame/img-03.webp" width="1248" height="1664" loading="lazy" alt="Start frame: Jeff standing on his board on the flat concrete of a skatepark, framed from the chest down" />
  </figure>
  <div class="frame-pair__arrow" aria-hidden="true"></div>
  <figure class="frame-pair__item frame-pair__item--result">
    <figcaption class="frame-pair__label">The clip it produced</figcaption>
    <video controls="" playsinline="" preload="metadata" width="1248" height="1664" poster="/blog/assets/posts/what-is-a-start-frame/img-03.webp" src="/blog/assets/posts/what-is-a-start-frame/vid-kickflip.mp4"></video>
  </figure>
</div>
<p><span class="post-loop-caption">Same character, same prompt, feet on the ground. The model builds the whole trick from there instead.</span></p>

<p>The still in each pair is not an illustration of the video next to it. It <strong>is</strong> that video’s first frame, which is why the two look identical until you press play. That is the thing worth taking away: the model did not interpret the image, it continued it.</p>

<p>Two clips, one prompt, two completely different shots. The start frame is what separated them.</p>

<hr />

<h2 id="what-makes-a-good-start-frame">What makes a good start frame</h2>

<p>A start frame only helps if it is the right kind of image. The model extends the frame you give it, it does not reinterpret it, so three things matter.</p>

<p><strong>Match your intended shot.</strong> If you need a close-up, start with a frame that is already close up. It will not zoom in for you.</p>

<p><strong>Keep it clean and high resolution.</strong> A blurry or low-res start frame carries that quality into the whole video. It does not correct itself as the generation continues.</p>

<p><strong>Keep it unambiguous.</strong> A cluttered composition hands the model uncertainty at the foundation, and that tends to compound rather than resolve.</p>

<p>Not sure which model to reach for, or how each handles frame options? The <a href="https://mito.ai/models/?type=image">image model guide</a> and <a href="https://mito.ai/models/?type=video">video model guide</a> break down what each one actually supports.</p>

<hr />

<h2 id="not-every-model-handles-this-the-same-way">Not every model handles this the same way</h2>

<p>Start frames are not one-size-fits-all. Different video models have their own cadence for how they use a starting image, and some support <strong>end frames</strong> too, letting you lock both where a clip begins and where it lands.</p>

<p>If you are choosing between models, check what frame options each supports before you build a workflow around it.</p>

<hr />

<p><strong>The short version.</strong> A start frame is literally frame one, not a vibe reference. Keep it clean, high resolution, and already framed like the shot you are going for, and you have traded guesswork for control.</p>

<p>A start frame is also one piece of keeping a character steady across a whole sequence. The rest of that method is in <a href="/blog/how-to-keep-ai-video-characters-consistent/">How to Keep AI Video Characters Consistent</a>.</p>

<p><a href="https://app.mito.ai/">Try it in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[A start frame is the exact image a model treats as frame one of your video. What it does, what makes a good one, and why models differ.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/what-is-a-start-frame/preview.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/what-is-a-start-frame/preview.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Best AI Music Generator for Video in 2026</title><link href="https://mito.ai/blog/best-ai-music-generator-for-video/" rel="alternate" type="text/html" title="Best AI Music Generator for Video in 2026" /><published>2026-09-21T00:00:00+02:00</published><updated>2026-09-21T00:00:00+02:00</updated><id>https://mito.ai/blog/best-ai-music-generator-for-video</id><content type="html" xml:base="https://mito.ai/blog/best-ai-music-generator-for-video/"><![CDATA[<p>Most “best AI music generator” lists rank tools by how good the output sounds. For video work that is the wrong first question. They all sound broadly fine now, and none of them sound like what you wanted on the first try.</p>

<p>What actually decides it is shape: how the tool charges you, where commercial rights begin, and whether you get stems.</p>

<p>A new option just landed that makes the pricing question sharper than it was. <strong>Google Lyria 3.5 is live in MITO</strong>, and it charges a flat fee per generation regardless of length.</p>

<hr />

<h2 id="what-lyria-35-brings-to-the-table">What Lyria 3.5 brings to the table</h2>

<p><strong>You can steer it.</strong> Tempo, instruments, vocal style, song structure, down to timing cues for builds and transitions. Before, you described a mood and hoped.</p>

<p><strong>Vocals stopped sounding robotic.</strong> They are more expressive, and the model takes image prompts, so you can point it at a scene and have the music follow its visual mood.</p>

<p><strong>Tracks run to three minutes.</strong> As one continuous piece, not short clips you stitch together afterwards.</p>

<hr />

<h2 id="the-three-pricing-shapes">The three pricing shapes</h2>

<p>Every tool in this category prices itself one of three ways, and the difference matters more than any feature.</p>

<table>
  <thead>
    <tr>
      <th>Shape</th>
      <th>What you pay</th>
      <th>Suits</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Per generation, flat</strong></td>
      <td>Same price at any length</td>
      <td>Long cues, few revisions</td>
    </tr>
    <tr>
      <td><strong>Per second</strong></td>
      <td>Scales with duration</td>
      <td>Short stings, heavy iteration</td>
    </tr>
    <tr>
      <td><strong>Subscription</strong></td>
      <td>Monthly credit allowance</td>
      <td>Steady daily volume</td>
    </tr>
  </tbody>
</table>

<p>Inside MITO the first two sit side by side, which makes the comparison concrete:</p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Lyria 3.5</th>
      <th>ElevenLabs Music</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Pricing</strong></td>
      <td>Fixed, any length</td>
      <td>9 credits per second</td>
    </tr>
    <tr>
      <td><strong>10 seconds</strong></td>
      <td>80 credits</td>
      <td>90 credits</td>
    </tr>
    <tr>
      <td><strong>60 seconds</strong></td>
      <td>80 credits</td>
      <td>540 credits</td>
    </tr>
    <tr>
      <td><strong>3 minutes</strong></td>
      <td>80 credits</td>
      <td>1,620 credits</td>
    </tr>
  </tbody>
</table>

<p><strong>The crossover is about nine seconds.</strong> Under that, per-second wins. Over it, flat wins, and the gap widens fast.</p>

<p>Suno and ElevenLabs sold direct both work the third way: a monthly fee buys a credit allowance you draw down.</p>

<hr />

<h2 id="where-commercial-rights-actually-begin">Where commercial rights actually begin</h2>

<p>This is the most-asked question in the category and the one most comparisons skip.</p>

<p><strong>On a free plan you generally do not have commercial rights.</strong> Suno’s free plan lists “No commercial rights” outright. ElevenLabs includes a commercial licence and music commercial use from its Starter plan, not on free.</p>

<p>The practical rule: free tiers are for auditioning the model. The moment a track goes near a client you need to be on a paid plan, and you need to have read that plan’s terms. This is not a detail to sort out after the edit is locked.</p>

<p>Two further things a brand’s legal team will ask before they ask about sound:</p>

<p><strong>What was it trained on?</strong> Google states Lyria was trained on licensed material that YouTube and Google had rights to use, and blocks prompts for named artists’ voices and copyrighted lyrics. Not every model makes that claim, and the ones that do not are a harder conversation.</p>

<p><strong>Is it watermarked?</strong> Lyria output carries SynthID, an imperceptible marker designed to survive re-encoding. It identifies audio as AI-generated. Worth saying plainly: it is not a licence and it clears nothing.</p>

<hr />

<h2 id="stems-and-why-they-decide-it-for-video">Stems, and why they decide it for video</h2>

<p>For a song, a stereo mix is the deliverable. For video, it usually is not.</p>

<p>The moment there is a voiceover you need to duck the music under it, and doing that on a flat mix means fighting the whole track instead of pulling one element down. Stems are the difference between a five-minute fix and a re-generate.</p>

<p>Suno separates stems on paid plans: two types on Pro, three on Premier. If a tool does not offer stems, that is a real constraint on client work, whatever it sounds like.</p>

<hr />

<h2 id="length-and-the-review-cost-nobody-budgets">Length, and the review cost nobody budgets</h2>

<p>A three-minute cue generated as one continuous piece holds under a long sequence without an obvious loop point. That is the case for Lyria’s length.</p>

<p>The cost nobody plans for: a three-minute track takes three minutes to actually listen to before you can approve it. On a flat per-generation price there is no reason not to generate the full length, so budget the review time. Two rounds on a three-minute cue is twelve minutes of listening, not two.</p>

<p>The same flat fee cuts the other way on short work. If you are iterating on a four-second sting you pay full freight every regeneration, so write a longer prompt and get further in one pass rather than nudging it repeatedly.</p>

<hr />

<h2 id="so-which-one">So which one</h2>

<p><strong>Scoring a film, a brand piece, anything over about a minute.</strong> Flat per-generation pricing, so Lyria 3.5. The length is free and the number does not move.</p>

<p><strong>Short stings, UI sounds, social cutdowns under ten seconds.</strong> Per-second pricing is genuinely cheaper, so ElevenLabs Music. Below the crossover the maths favours it.</p>

<p><strong>Producing music all day, every day, as the main job.</strong> A subscription with a monthly allowance fits better than per-use pricing, so Suno or ElevenLabs direct. You are optimising for volume, not per-track cost.</p>

<p><strong>Client work of any kind.</strong> Whichever tool you pick, be on a paid plan, get stems, and be able to answer the provenance question before anyone asks it.</p>

<hr />

<h2 id="a-note-on-prices">A note on prices</h2>

<p>Every figure a comparison post quotes goes stale, and vendor pricing varies by region and by monthly versus annual billing. Suno’s page quotes euros in Europe and dollars in the US, for the same plan. Check the vendor’s own page in your currency before you commit: <a href="https://suno.com/pricing">Suno</a>, <a href="https://elevenlabs.io/pricing">ElevenLabs</a>.</p>

<p>The pricing <em>shapes</em> change far more slowly than the numbers, which is why this post is built on those.</p>

<hr />

<p>Lyria 3.5 and ElevenLabs Music both run inside MITO, so you can switch between the two pricing shapes without switching tools.</p>

<p><a href="https://app.mito.ai/">Open MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[Lyria 3.5, ElevenLabs Music and Suno compared for video work: pricing shape, where commercial rights begin, track length, stems and provenance.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/best-ai-music-generator-for-video/hero.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/best-ai-music-generator-for-video/hero.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">How to Keep AI Video Characters Consistent</title><link href="https://mito.ai/blog/how-to-keep-ai-video-characters-consistent/" rel="alternate" type="text/html" title="How to Keep AI Video Characters Consistent" /><published>2026-09-16T00:00:00+02:00</published><updated>2026-09-16T00:00:00+02:00</updated><id>https://mito.ai/blog/how-to-keep-ai-video-characters-consistent</id><content type="html" xml:base="https://mito.ai/blog/how-to-keep-ai-video-characters-consistent/"><![CDATA[<p>If you have generated more than a handful of AI video clips, you already know the problem. Your character looks right in the first scene, then the face, outfit or build quietly drifts by the third shot. Technically it is the same character. It does not feel like it.</p>

<p>Here is the method we use in MITO to stop that happening.</p>

<p><img src="/blog/assets/posts/keep-ai-characters-consistent/img-01.jpg" alt="The same character held steady across shots: a desert mechanic in goggles, a rust-red scarf and a worn canvas vest" /></p>

<hr />

<h2 id="why-consistency-breaks-in-the-first-place">Why consistency breaks in the first place</h2>

<p>Every generation is independent by default.</p>

<p>The model is not remembering your character between shots unless you deliberately anchor it to something. No anchor, no consistency. That is the whole problem, and naming it plainly is what makes the fix land.</p>

<hr />

<h2 id="building-the-anchor">Building the anchor</h2>

<p>The technique comes down to one move. Generate a single strong reference image first, your character’s best possible still, and reuse that exact image as the anchor for every shot after it.</p>

<p>In MITO, this is what <a href="/blog/introducing-director/">Director</a> is doing under the hood. It builds its own character identity and scene references before generating a film, which is why its output holds together scene to scene. You can do the same thing deliberately with Elements.</p>

<p>If you are working purely off prompt discipline rather than a saved-reference feature, the equivalent is to lock a style block: wardrobe, lighting language, lens language, location. Then reuse that block word for word on every shot. Consistency is not just the face. It is everything around the character holding steady too.</p>

<p>Not sure which model to reach for at each stage? The <a href="https://mito.ai/models/?type=image">image model guide</a> and <a href="https://mito.ai/models/?type=video">video model guide</a> break down what each one is actually good at, so you are not guessing.</p>

<p><img src="/blog/assets/posts/keep-ai-characters-consistent/img-02.jpg" alt="A character reference sheet: full-body front view on plain white, a three-quarter working shot, a side view, and front and profile face close-ups" /></p>

<hr />

<h2 id="where-elements-come-in">Where Elements come in</h2>

<p>Elements are MITO’s answer to “how do I make the model remember my character”. The Elements panel has dedicated slots for Characters, Locations and Objects, so you are not retyping a description and hoping the model reads it the same way twice. You lock in a visual identity once and pull it back into every generation after that.</p>

<p>There are two ways to build one.</p>

<p><strong>Let Director build it with you.</strong> Describe who the character is, what they look like, their build, their style, and Director translates that into an Element. Faster if you are still working out what the character should look like.</p>

<p><strong>Build it from scratch.</strong> Open the Element card, select Character, upload your own reference images and write your prompt in full detail. Better if you already have a clear reference and want control from the start.</p>

<p>Either way, do not stop at one image. Generate more angles: sitting, standing, turned to the side. Switch the background to plain white so you are isolating the character rather than the scene. Once it is built, reference it by name with the <strong>@</strong> symbol in every prompt after that, and MITO pulls in the locked reference instead of guessing again from text.</p>

<p><img src="/blog/assets/posts/introducing-elements/elements-newsletter.gif" alt="The MITO canvas, adding a Character Element with image references attached" loading="lazy" /></p>

<p>The full breakdown is in <a href="/blog/introducing-elements/">Keep the same character in every shot</a>.</p>

<hr />

<h2 id="the-trick-nobody-talks-about-negative-constraints">The trick nobody talks about: negative constraints</h2>

<p>Most advice is about what to tell the model to do. The underused half is what to tell it to stop doing.</p>

<p>A negative constraint removes a specific drift artifact in real time. An extra finger. A changed jacket colour. A face that is subtly off. It is often the difference between a shot that reads as consistent and one that does not.</p>

<blockquote>
  <p>no eye glasses, no leather gloves, no change in his beard coloring</p>
</blockquote>

<p>Half of looking consistent is just telling the model what not to invent.</p>

<p><img src="/blog/assets/posts/keep-ai-characters-consistent/negative-constraints.gif" alt="A negative constraint applied mid-generation, removing the drift artifact without changing the rest of the shot" />
<span class="post-loop-caption">A negative constraint applied mid-generation, removing the drift artifact without touching the rest of the shot.</span></p>

<hr />

<h2 id="close-the-loop">Close the loop</h2>

<p>The best version of this does not teach the method and stop. It returns to the opening shot and labels it: same anchor, same style block, same constraint, right there on screen. That callback is what makes the lesson stick instead of feeling like disconnected tips.</p>

<p>Want to see the full method in action? Here is the whole thing, start to finish, in MITO.</p>

<div class="yt-embed">
  <iframe src="https://www.youtube-nocookie.com/embed/D7M3zRIaGlQ" title="YouTube video player" frameborder="0" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen="" loading="lazy"></iframe>
</div>

<hr />

<p><strong>The short version.</strong> One strong reference. One locked style block. One well-placed negative constraint. Reused identically across every shot.</p>

<p>That is the entire method. Everything else is just how well you show it.</p>

<p><a href="https://app.mito.ai/">Build your first Character Element →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[The method: one strong reference image, one locked style block, one negative constraint, reused identically across every shot.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/keep-ai-characters-consistent/hero.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/keep-ai-characters-consistent/hero.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Conspiracy Gnome: one unbroken shot, consistent AI character</title><link href="https://mito.ai/blog/conspiracy-gnome-suspicious-mailman/" rel="alternate" type="text/html" title="Conspiracy Gnome: one unbroken shot, consistent AI character" /><published>2026-09-15T00:00:00+02:00</published><updated>2026-09-15T00:00:00+02:00</updated><id>https://mito.ai/blog/conspiracy-gnome-suspicious-mailman</id><content type="html" xml:base="https://mito.ai/blog/conspiracy-gnome-suspicious-mailman/"><![CDATA[<p>Day 47. The mailman is back, same time, same route. A terracotta gnome in a crimson knitted hat watches him from behind a flowerpot, pins a fresh leaf to a miniature evidence board strung with red twine, and concludes what he has concluded every day for forty-seven days. The sprinklers went off four minutes early. That is not a coincidence.</p>

<p>Episode 1 of Conspiracy Gnome is a single unbroken tracking shot. No cuts, no jump cuts, one continuous glide through a cluttered cottage garden at golden hour. Which means the gnome’s hat, skin tone, eyes and tunic had to look identical at second 29 as they did at second 1, with nowhere to hide a mistake.</p>

<p>Here is the pipeline, the full prompt, and the three things that fought back.</p>

<h2 id="the-brief">The brief</h2>

<p>The Suspicious Mailman is dry mockumentary comedy told almost entirely through camera movement. A lookout gnome. A mail carrier who never notices him. A freeze-frame “CASE UNSOLVED” stamp as the punchline.</p>

<p>The constraint that shaped every other decision was continuity. One take. No editing tricks to cover a mistake. Zero visual drift on either character across eight timed narrative beats.</p>

<p><img src="/blog/assets/posts/conspiracy-gnome-suspicious-mailman/img-01.jpg" alt="Reference still: cluttered cottage garden at golden hour, mossy path to a cream-painted front door, teacup planters, a red-and-cream pinwheel and a rusted bicycle wheel" /></p>

<h2 id="the-pipeline">The pipeline</h2>

<p><a href="/blog/introducing-director/">Director</a> picked the models and settings instead of the team assembling the stack by hand.</p>

<ul>
  <li><strong>Images: Grok Imagine, 2K.</strong> Reference stills for the gnome, the mailman and the practical evidence board, generated before the shoot so every later beat had a fixed visual anchor to match against.</li>
  <li><strong>Video and audio: Seedance 2.5.</strong> The full continuous shot, including wind chimes, footsteps and the gravelly whispered voiceover, generated together rather than layered in afterwards.</li>
  <li><strong>Titles: ChatGPT Images 2.5, Flare.</strong> The logo card. Chunky 3D block letters, knit-felt texture, sage-green background.</li>
</ul>

<p><img src="/blog/assets/posts/conspiracy-gnome-suspicious-mailman/img-02.jpg" alt="Conspiracy Gnome logo in chunky 3D block letters with a knit-felt texture, cream and tan with a deep rust-red outline, on a sage-green background" /></p>

<h2 id="what-fought-back">What fought back</h2>

<h3 id="design-drift">Design drift</h3>

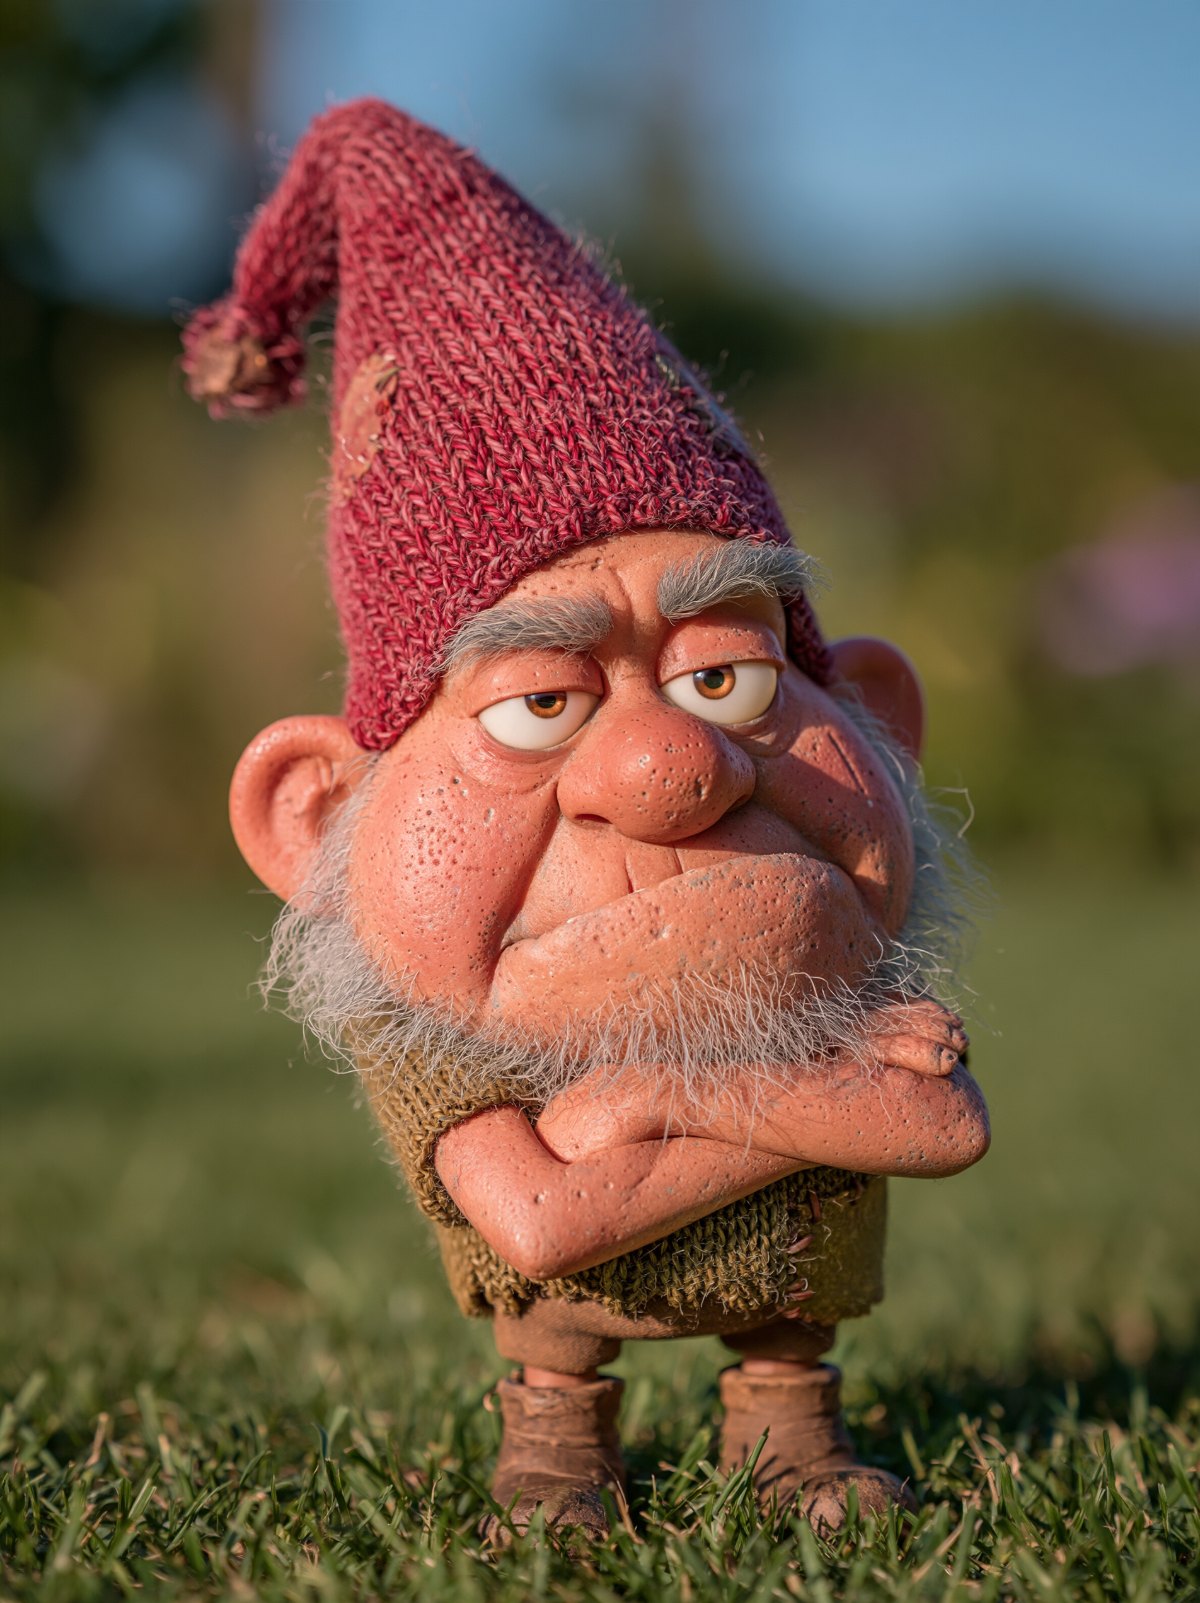
<p>Nothing about either character could be allowed to wander between beats. Same terracotta tone, same hat, same satchel, same face.</p>

<p>The fix was blunt repetition. Rather than describing each character once and trusting the model to hold it, the exact proportions, colours, materials and clothing were restated in every single beat of the prompt. Not just the first one. It makes the prompt long and repetitive to read, and that is the point.</p>

<p><img src="/blog/assets/posts/conspiracy-gnome-suspicious-mailman/img-03.jpg" alt="Stylized 3D garden gnome with a crimson knitted hat, bushy grey beard and folded arms, standing on grass in golden-hour light" /></p>

<h3 id="the-mailmans-pace">The mailman’s pace</h3>

<p>Left alone, the model kept pulling his walk towards a slow cinematic drift. Technically beautiful, wrong for the joke. A mailman who floats is a mailman the audience reads as significant, and the whole gag depends on him being aggressively ordinary.</p>

<p>The prompt had to override it out loud: “moving at real walking speed rather than slow motion,” repeated at every beat he appears in.</p>

<h3 id="staying-hidden-inside-one-take">Staying hidden inside one take</h3>

<p>With no cuts to hide a blocking mistake, the gnome’s hide-and-peek staging had to be choreographed into the camera path itself. The exact moment he ducks behind the flowerpot is timed to the exact moment the camera reveals the mailman, in the same continuous glide.</p>

<h3 id="vertical-was-not-a-crop">Vertical was not a crop</h3>

<p>The 9:16 cut was not made by cropping the finished horizontal edit. The same beats were re-prompted natively for the vertical frame, so the composition and blocking hold on their own instead of reading as a squeezed version of something else.</p>

<h3 id="voiceover-timing">Voiceover timing</h3>

<p>Each whispered line had to land inside its own timecoded window, 0:05 to 0:08, 0:08 to 0:11, and so on, at a natural unhurried pace. The lesson is the same one that shows up on every timed voiceover: give the line room inside its window rather than rushing it to fit.</p>

<p><img src="/blog/assets/posts/conspiracy-gnome-suspicious-mailman/img-04.jpg" alt="Reference still: miniature conspiracy evidence board at garden-gnome scale, red twine linking squirrel photos, handwritten notes, an acorn and a sprinkler diagram" /></p>

<h2 id="the-prompt">The prompt</h2>

<p>Three reference images were built first and cited throughout the video prompt.</p>

<p><strong>Evidence board:</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Photorealistic miniature conspiracy evidence board built at garden-gnome scale, two thin weathered wooden stakes with red twine connecting tiny printed photos, a squirrel photograph, a real acorn, a small sprinkler timer diagram, dried leaves, miniature handwritten notes, tiny pushpins, positioned among moss and flowerpots in a real sunlit garden, practical handmade prop, macro cinematography, realistic materials, warm golden-hour light, analog film grain, no character, no readable text.
</code></pre></div></div>

<p><strong>Garden:</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Photorealistic live-action suburban cottage garden at warm golden hour, lovingly cluttered rather than messy, mossy stone path leading to a cream-painted front door, mismatched vintage brass lanterns, chipped porcelain teacups used as planters, striped red-and-cream pinwheel slowly turning, old rusty bicycle wheel with wildflowers growing through its spokes, flowering terracotta pots, soft lawn, dense hydrangeas and daisies, subtle wind chimes, rich saturated retro postcard color grade, analog 35mm texture, shallow depth of field, natural afternoon sunlight, cinematic mockumentary production design, no people, no gnomes.
</code></pre></div></div>

<p><strong>Title card:</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>A cartoon show title logo reading "Conspiracy Gnome" in massive chunky 3D block letters, tilted slightly like a comic-book shout, warm cream lettering with a thick deep-rust-red outline and soft matte drop shadow, letters have a subtle matte knit-felt texture, set on a flat solid sage-green background. No gnome, no character icon, no other text.
</code></pre></div></div>

<p><strong>The full shot, Seedance 2.5.</strong> Note how often the character description repeats. That repetition is what holds the design steady.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>A single unbroken 30-second continuous tracking shot moves fluidly through a lovingly cluttered warm suburban cottage garden at golden hour, weaving between locations and characters with smooth camera glides and pushes. No hard cuts, no jump cuts, realistic handheld-documentary camera language throughout. Maintain exact, unwavering visual consistency of both the gnome and the mailman across every beat: identical proportions, colors, materials, and clothing from start to finish, with no drift in their design.

0:00-0:03 - The camera glides forward in a slow push over the garden: mismatched vintage brass lanterns, chipped porcelain teacups used as planters, a striped red-and-cream pinwheel spinning lazily, an old rusty bicycle wheel with wildflowers growing through its spokes. Ambient sound only: wind chimes, birds, a soft breeze.

0:03-0:05 - The camera drifts smoothly across a row of ordinary decorative garden gnomes lined up along the flowerbed, each sculpted in a similar terracotta style with small knitted hats, completely motionless, and holds a beat too long on one of them: the protagonist gnome, with faded warm terracotta skin, oversized soulful brown eyes, a floppy hand-knitted crimson-red pointed hat, and a knitted moss-green tunic. His eyes flick subtly sideways and the brim of his hat gives a barely perceptible twitch. Score drops to near silence.

0:05-0:08 - The camera pushes into an extreme close-up on his eyes narrowing with suspicious determination, same exact face and hat design. Score kicks in low and ominous. Gravelly whispered voiceover: "Day 47. He's back."

0:08-0:11 - The camera pulls back and glides toward the garden path, revealing the friendly postal worker, same navy uniform, canvas mail satchel, and face as established, walking with a natural, brisk, believable pace up the path, moving at real walking speed rather than slow motion. Just before the mailman comes into view, the protagonist gnome quickly and quietly repositions himself into a lookout stance behind a weathered terracotta flowerpot, tucked completely out of the mailman's line of sight, peering out cautiously with a tiny brass magnifying glass, careful never to be seen. Gravelly whispered voiceover: "Same time. Same route. That's exactly what they WANT you to think."

0:11-0:15 - The camera moves fluidly to the gnome's miniature conspiracy evidence board, thin wooden stakes strung with red twine, a photo of a squirrel, a real acorn, a small sprinkler timer diagram, dried leaves, tiny handwritten notes, as he frantically pins a fresh leaf to it, his appearance still identical to every earlier beat. Gravelly whispered voiceover: "Sprinklers went off four minutes early today. Coincidence? I don't think so."

0:15-0:18 - The camera glides back toward the cream front door as the postal worker, moving at the same natural brisk pace, same uniform and satchel, drops a stack of mail through the brass mail slot, completely normal and unhurried in his own manner, without ever noticing the gnome. The gnome, who has kept himself hidden in his lookout position the whole time, gasps and ducks further out of sight behind the flowerpot at the last second. Gravelly whispered voiceover: "He knows that I know."

0:18-0:22 - The camera pushes into a close-up on the gnome, same consistent design throughout, standing beside the pile of delivered mail. A plain unbranded colorful flyer flutters loose from the pile. His eyes go huge with sincere existential alarm, freezing in a startled pose. The frame freezes, and a bold vintage rubber-stamp graphic slams down across the image in distressed red stamped ink, reading "CASE UNSOLVED", a single intentional in-world stamp graphic, with a satisfying thud sound effect on impact.

Throughout: rich saturated retro postcard color grade, warm golden-hour light, analog 35mm film texture, dry mockumentary comedy tone, continuous unbroken camera movement connecting every beat, consistent character design from first frame to last, the mailman always moving naturally and believably at real walking speed, the gnome always staying hidden from the mailman's view like a careful lookout. No readable text anywhere except the intentional "CASE UNSOLVED" stamp in the final freeze frame.
</code></pre></div></div>

<h2 id="what-we-took-from-it">What we took from it</h2>

<p>Character consistency in a continuous shot is not really a model problem. It is a prompt discipline problem. The model will hold a design for as long as you keep telling it what the design is, and it will start improvising the moment you stop.</p>

<p>The same applies to pace, to staging, and to anything else you assumed was established. If it matters at second 29, write it again at second 29.</p>

<p>Elements now does the repeating for you. Define a Character once and bring it into every scene instead of restating it by hand, which is the same fix made permanent. See <a href="/blog/introducing-elements/">Introducing Elements</a>.</p>

<p>Conspiracy Gnome is an original MITO series. Episode 2 is in production.</p>

<p><a href="https://app.mito.ai/">Build your first Character on MITO →</a></p>]]></content><author><name>Macarena Rico and Ruth Fernández</name></author><category term="crafted-stories" /><summary type="html"><![CDATA[Inside MITO: how Director, Seedance 2.5 and ChatGPT Images 2.5 built Conspiracy Gnome Ep. 1 as one unbroken shot, and what nearly broke it.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/conspiracy-gnome-suspicious-mailman/hero.jpg" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/conspiracy-gnome-suspicious-mailman/hero.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Flare vs. Sunburst: Which ChatGPT Images 2.5 Model Should You Use?</title><link href="https://mito.ai/blog/chatgpt-images-2-5-flare-vs-sunburst/" rel="alternate" type="text/html" title="Flare vs. Sunburst: Which ChatGPT Images 2.5 Model Should You Use?" /><published>2026-09-11T00:00:00+02:00</published><updated>2026-09-11T00:00:00+02:00</updated><id>https://mito.ai/blog/chatgpt-images-2-5-flare-vs-sunburst</id><content type="html" xml:base="https://mito.ai/blog/chatgpt-images-2-5-flare-vs-sunburst/"><![CDATA[<p><strong>CHATGPT IMAGES 2.5</strong></p>

<h2 id="another-week-another-ai-model-launch">Another week, another AI model launch</h2>

<p>The biggest difference this time is that editing finally starts feeling more like… editing.</p>

<p>OpenAI says ChatGPT Images 2.5 improves reference-image preservation, multi-turn editing and generation speed, with latency reduced by up to 50% compared with Images 2.0.</p>

<p>What changes in practice:</p>

<ul>
  <li><strong>Edit what you asked for.</strong> Change one thing without accidentally changing five others. The rest of the image stays much more stable.</li>
  <li><strong>Keep previous edits intact.</strong> A few rounds of feedback no longer make your original image slowly disappear.</li>
  <li><strong>Wait less between revisions.</strong> Up to 50% lower latency makes the back-and-forth on tiny client requests much faster.</li>
</ul>

<hr />

<h2 id="two-models-depending-on-what-youre-doing">Two models, depending on what you’re doing</h2>

<p>You probably don’t need maximum fidelity for every generation.</p>

<p>Sometimes you’re throwing fifteen ideas at the wall. Other times, the client has approved everything except one tiny detail.</p>

<ul>
  <li><strong>Flare</strong> — for exploring ideas quickly. Moodboards, colorways, variations and quick creative exploration.</li>
  <li><strong>Sunburst</strong> — for protecting a nearly-finished asset. Detailed edits, campaign assets and final client revisions.</li>
</ul>

<p>Think of <strong>Flare</strong> as <em>“show me more options.”</em></p>

<p>And <strong>Sunburst</strong> as <em>“please, for the love of God, don’t touch anything else.”</em></p>

<hr />

<h2 id="a-few-specs-worth-knowing">A few specs worth knowing</h2>

<p>If you care less about model names and more about what you can actually get out of them, there are a few useful upgrades too:</p>

<ul>
  <li><strong>More quality levels:</strong> alongside <code class="language-plaintext highlighter-rouge">low</code>, <code class="language-plaintext highlighter-rouge">medium</code> and <code class="language-plaintext highlighter-rouge">high</code>, you now get <code class="language-plaintext highlighter-rouge">xhigh</code> and <code class="language-plaintext highlighter-rouge">max</code> when you need more detail.</li>
  <li><strong>Up to 4K output:</strong> useful when the image is heading somewhere beyond a moodboard or social post.</li>
  <li><strong>Transparent backgrounds:</strong> generate transparent PNG or WebP assets directly, especially useful for product shots and compositing.</li>
  <li><strong>Built-in provenance:</strong> supported generated images can include C2PA metadata and an invisible SynthID watermark.</li>
</ul>

<p>Basically: more control over how polished the output needs to be, without treating every generation like a final render.</p>

<hr />

<h2 id="what-still-isnt-perfect">What still isn’t perfect</h2>

<p>The editing is much better, but there are still a few things to watch:</p>

<ul>
  <li><strong>Preserved does not always mean untouched:</strong> an area can look identical after an edit while still having small pixel-level changes underneath.</li>
  <li><strong>Logos and approved brand assets still need care:</strong> if something must remain technically identical, keep the original asset locked and composite the edited part back into it instead of regenerating the whole image.</li>
  <li><strong>Edit boundaries are not perfectly strict:</strong> OpenAI notes that image-edit selections act as guidance, so changes can sometimes affect areas outside the region you selected. See <a href="https://help.openai.com/en/articles/11084440-images-in-chatgpt">OpenAI’s image editing guide</a>.</li>
  <li><strong>Grain and texture can still appear:</strong> some early independent tests have reported subtle noise on flat gradients, skies and studio-style backgrounds after generation or repeated edits. This is not an officially documented OpenAI limitation, but it is worth checking before calling an asset final. <a href="https://freyavideo.com/blog/gpt-image-2-5-noise-editing">See an early independent test</a>.</li>
</ul>

<p>In short: visually consistent is much better. Mathematically identical is still getting there.</p>

<hr />

<h2 id="use-it-inside-your-mito-workflow">Use it inside your MITO workflow</h2>

<p>Both models are now available in MITO.</p>

<p>You can combine them with your existing references and <a href="/blog/introducing-elements/">Elements</a> to keep characters, products, locations and other visual details consistent across iterations.</p>

<p>And when describing a composition in words becomes painful, use a rough sketch or storyboard as a visual reference instead.</p>

<p><a href="https://app.mito.ai/">Try ChatGPT Images 2.5 in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[ChatGPT Images 2.5 brings Flare and Sunburst to MITO, with better reference preservation, multi-turn editing and up to 50% lower latency.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/chatgpt-images-2-5-flare-vs-sunburst/hero.png" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/chatgpt-images-2-5-flare-vs-sunburst/hero.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Gemini Omni 1.1 Flash: stop describing movement. Show it.</title><link href="https://mito.ai/blog/direct-ai-video-motion-with-phone-footage/" rel="alternate" type="text/html" title="Gemini Omni 1.1 Flash: stop describing movement. Show it." /><published>2026-09-08T00:00:00+02:00</published><updated>2026-09-08T00:00:00+02:00</updated><id>https://mito.ai/blog/direct-ai-video-motion-with-phone-footage</id><content type="html" xml:base="https://mito.ai/blog/direct-ai-video-motion-with-phone-footage/"><![CDATA[<p><strong>GEMINI OMNI 1.1 FLASH</strong></p>

<h2 id="stop-describing-movement-show-it">Stop describing movement. Show it.</h2>

<p>Getting a person to move naturally is hard to explain in a text box.</p>

<p>With Gemini Omni Flash 1.1, you can film a quick movement on your phone and use that clip as visual direction for the shot.</p>

<p>Show the model how to dance instead of trying to explain it over the phone.</p>

<p>You keep the movement and feel you liked, while directing the character, world, and camera around it.</p>

<p>If the same character, product, or location needs to carry through more than one shot, set it up as a reusable <a href="/blog/introducing-elements/">MITO Element</a> before you direct the movement.</p>

<hr />

<h2 id="the-workflow">The workflow</h2>

<ol>
  <li>Film the movement on your phone.</li>
  <li>Add it to your MITO project.</li>
  <li>Tell MITO who is in the shot and where they are.</li>
  <li>Generate.</li>
  <li>Review the movement, fix one thing, and go again.</li>
</ol>

<p>The reference gives Omni the motion. Your direction sets the character, action, camera, and world around it.</p>

<hr />

<h2 id="edit-it-just-by-asking">Edit it just by asking</h2>

<p>“Make the jacket yellow. Keep everything else the same.”</p>

<p>That’s it. You don’t have to rethink the whole shot for one tiny change.</p>

<p>Treat the reference as direction, then refine the one part of the motion or camera feel that matters most.</p>

<p>Gemini’s <a href="https://ai.google.dev/gemini-api/docs/omni#using_tags_in_prompts_to_set_image_and_video_roles">official Omni Flash guide</a> explains how image and video references work; uploaded video-reference audio is not used.</p>

<hr />

<h2 id="keep-the-scene-going">Keep the scene going</h2>

<p>You can extend the same scene in 10-second chunks, all the way to 40 seconds.</p>

<p>That is useful when you already have the movement and world working and want to carry the moment forward instead of rebuilding the shot from scratch.</p>

<p>Google documents the <a href="https://ai.google.dev/gemini-api/docs/omni#extension_constraints_and_guidelines">extension constraints</a>, including regional limits for uploaded-video extension.</p>

<hr />

<h2 id="keep-the-direction-clear">Keep the direction clear</h2>

<p>Give Omni four essentials:</p>

<ol>
  <li><strong>Who or what are we watching?</strong></li>
  <li><strong>What are they doing?</strong></li>
  <li><strong>What is the camera doing?</strong></li>
  <li><strong>What should it feel and sound like?</strong></li>
</ol>

<p>One clear idea beats twelve ideas fighting each other.</p>

<p>For a broader walkthrough of prompting, editing, and reference media, read <a href="/blog/how-to-prompt-gemini-omni-on-mito/">How to prompt Gemini Omni on MITO</a>.</p>

<hr />

<h2 id="where-it-still-needs-your-eyes">Where it still needs your eyes</h2>

<p>Fast hands, tiny product text, busy crowds, and too many simultaneous changes are still hard for video models.</p>

<p>If the shot matters, make fewer things happen. If the character matters, give it a good reference. If sound matters, listen to the whole clip instead of judging it from the thumbnail.</p>

<p>Need a product-led shot, readable text, approved references, or sound that carries the idea? Try <a href="/blog/minimax-h3-max-ai-video/">MiniMax H3 Max</a>.</p>

<p><a href="https://app.mito.ai/">Try Gemini Omni Flash 1.1 in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[Use real footage as motion reference, edit AI video by describing the change, and extend a Gemini Omni 1.1 Flash scene in MITO.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/direct-ai-video-motion-with-phone-footage/hero.png" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/direct-ai-video-motion-with-phone-footage/hero.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">MiniMax H3 Max: faster than you can watch it</title><link href="https://mito.ai/blog/minimax-h3-max-ai-video/" rel="alternate" type="text/html" title="MiniMax H3 Max: faster than you can watch it" /><published>2026-09-08T00:00:00+02:00</published><updated>2026-09-08T00:00:00+02:00</updated><id>https://mito.ai/blog/minimax-h3-max-ai-video</id><content type="html" xml:base="https://mito.ai/blog/minimax-h3-max-ai-video/"><![CDATA[<p><strong>MINIMAX H3 MAX</strong></p>

<h2 id="it-can-generate-video-faster-than-you-can-watch-it">It can generate video faster than you can watch it</h2>

<p>A 5-second generation can finish in under 3 seconds.</p>

<p>People have already taken this to the obvious extreme by livestreaming and letting viewers prompt what happens next. Promptable live television is apparently a thing now.</p>

<p>If you test one thing first, try a timed sequence. That is where H3 Max starts to feel different.</p>

<hr />

<h2 id="direct-the-timeline">Direct the timeline</h2>

<p>Tell it “close-up at 2s, camera pulls back at 5s, character speaks at 7s” and it actually does it.</p>

<p>That matters when the timing is the idea, not an afterthought.</p>

<h2 id="show-it-what-has-to-stay-consistent">Show it what has to stay consistent</h2>

<p>Characters. Product shots. Motion references. Audio.</p>

<p>H3 Max can read those references together, which makes it much easier to tell the model what cannot drift while the shot changes around it.</p>

<hr />

<h2 id="h3-max-or-omni-flash">H3 Max or Omni Flash?</h2>

<p>Choose <strong>H3 Max</strong> when the shot needs precision: an approved product, controlled timing, legible text, or sound that carries the idea.</p>

<p>Choose <strong>Omni Flash</strong> when the hard part is movement: exploring a motion, changing a shot through conversation, or carrying the same scene forward.</p>

<p>A useful handoff is to find the movement in Omni, then use H3 Max for the product-led shot with the approved references and sound.</p>

<p>See the <a href="/blog/direct-ai-video-motion-with-phone-footage/">Gemini Omni Flash 1.1 motion-reference workflow</a> for the first half of that workflow.</p>

<hr />

<h2 id="choose-the-right-input-before-you-start">Choose the right input before you start</h2>

<p>H3 Max has two ways to work.</p>

<h3 id="use-frames">Use frames</h3>

<p>Use frames when you know how the shot starts or ends. Give it the first frame, the last frame, or both to guide the move between them.</p>

<h3 id="use-references">Use references</h3>

<p>Use references when it needs to understand a person, product, image, video, or sound. This is the better choice for a client product, a lead character, or a sound-led scene.</p>

<p>Choose one per shot. In MITO, frames and references are separate workflows.</p>

<p>Ask: do I need to control the move, or show it what the world looks like?</p>

<p>If you add an audio reference, include an image or video reference too.</p>

<p>If the same product, character, or place will recur, create it as a reusable <a href="/blog/introducing-elements/">MITO Element</a> first. That lets each H3 Max prompt focus on the shot rather than rebuilding the same brief.</p>

<hr />

<h2 id="where-it-still-needs-your-eyes">Where it still needs your eyes</h2>

<p>H3 Max gets you closer to the brief, but client-critical details still need review.</p>

<ul>
  <li><strong>Type:</strong> if a sign matters, state the exact words, where they sit, and how they should look. Check spelling and stability as the camera moves.</li>
  <li><strong>Products:</strong> use the approved image and name the details that must stay visible. Compare the final shot against the reference.</li>
  <li><strong>Sound:</strong> include it early when it is part of the idea, then listen to the full clip rather than judging from the thumbnail.</li>
</ul>

<p>Editing stills rather than generating video? <a href="/blog/chatgpt-images-2-5-flare-vs-sunburst/">ChatGPT Images 2.5 brings Flare and Sunburst to MITO</a>.</p>

<p><a href="https://app.mito.ai/">Try MiniMax H3 Max in MITO →</a></p>]]></content><author><name>The MITO Team</name></author><category term="tutorials" /><summary type="html"><![CDATA[MiniMax H3 Max generates AI video quickly, lets you direct the timeline, and understands approved references together in MITO.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://mito.ai/blog/assets/posts/minimax-h3-max-ai-video/hero.png" /><media:content medium="image" url="https://mito.ai/blog/assets/posts/minimax-h3-max-ai-video/hero.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>